app
Adom TTS: Text to Speech
Public Made by Adomby adom
Adom's shared voice service. Reads your AI's answers back to you while you drive, and renders perfectly-timed voiceover tracks for your demo videos, so you never record your own voice.
← Commit history
Publish 1.9.17
9 files changed
+137−102
Cargo.toml+1−1@@ -1,6 +1,6 @@ [package] name = "adom-tts"-version = "1.9.16"+version = "1.9.17" edition = "2021" license = "AGPL-3.0-or-later" repository = "https://github.com/adom-inc/adom-tts"
README.md+120−98@@ -1,99 +1,125 @@-# adom-tts+# Adom TTS — Text to Speech -**Adom's shared voice.** A thin Rust CLI + webview Playground for `service-tts` — the-edge-tts wrapper with Adom pronunciation overrides and a source-hash cache. It does two-things that matter day to day:+**Adom's shared voice.** A thin Rust CLI + a live player webview for `service-tts` —+the edge-tts wrapper with Adom pronunciation overrides and a source-hash cache. Your+AI speaks through it; you listen instead of read. -- **When you're driving** — it reads your AI's answers back to you, hands-free.-- **When you're making a demo** — it renders the video's voiceover track with exact- timing, so you never have to record your own voice.+## The three ways people actually use it +### 1. While you're driving (hands-free) -## The two use cases+You're in the car and can't read the screen. Just say: -### Drive mode (hands-free)+> "Read me your last answer, I'm driving." -You're in the car. You can't read the screen. Just say it:+Claude composes the reply, speaks it through the shared player, and — this is the+important part — **verifies you actually heard it**. Clips buffer through dead zones+and hotspot drops, retry if they never reached your ears, and land in a replayable+History if two updates arrive back-to-back. The full hands-free contract lives in the+[adom-tts skill](skills/adom-tts/SKILL.md) (also on this page's **Skills** tab) — it+triggers on the words you'd actually say: "read it to me", "read that back", "I'm in+the car", "narrate the answer", and many more. -> "Read me your last answer, I'm driving."+### 2. At your laptop, when you'd rather listen than read++You don't have to be driving. Long AI answers are tiring to read; tell your AI+"say it out loud" or "talk to me instead of writing" and every reply plays through+the player while you keep your eyes on your actual work. Parallel AI threads share+ONE player — clips queue in order, never talk over each other, and each one announces+which thread is speaking and what the update is about.++### 3. Demo-video voiceovers (exact timing, no recording booth)++Feed `adom-tts` a narration script and get a clean, perfectly-timed `.mp3` voiceover+track in the house voice (`en-US-AndrewNeural`). No retakes, no listening to your own+voice. Every clip is cached by source hash, so iterating on a script is instant after+the first render — which is why `demo-recording`, `video-post`, and every+tour/walkthrough tool route through it.++## What it looks like -Claude composes the reply, pipes it through `adom-tts say --play`, and it plays aloud —-no screen, no typing. The skill triggers on the words you'd actually use ("read it to-me", "read that back", "I'm in the car", "narrate the answer", and many more).+### The live player -### Demo voiceover (exact timing)+One shared player for all your AI threads. The header tells you WHO is speaking (the+thread) and WHAT the clip is about — here the `flight-search` thread is reading out+flight options. The transcript highlights word-by-word as it speaks, the version badge+shows which build is running, and the green light breathes while the AI's pipe to the+player is live. -Writing a walkthrough or product demo? Feed `adom-tts` your narration script and get a-clean, perfectly-timed `.mp3` voiceover track in the house voice (`en-US-AndrewNeural`).-No recording booth, no retakes, no listening to your own voice. Because every clip is-cached by source hash, iterating on the script is instant after the first render — which-is why `demo-recording`, `video-post`, and every tour/walkthrough tool route through it.+ +### The replayable History++Missed a clip because you drove through a dead zone, or two threads spoke back-to-back?+Every played clip is kept — with the sending thread, a one-line description, when it+played, and a replay button. Clips that never fully played are flagged, so the one you+missed is exactly the one that stands out. Tap the arrow and it plays again.++++### The verified send (what your AI runs)++Playback is never assumed. `--play` queues the clip and reports its queue position;+`--confirm` blocks until the player proves the audio reached you, end to end. Note the+required `--thread` and `--desc` — anonymous clips are refused, because a History full+of `reply.mp3` entries helps no one.++ ## Install ```bash-adompkg install adom-tts+adom-wiki pkg install adom/adom-tts adom-tts health # confirm the shared voice service is reachable ``` -That installs the CLI, the Claude Code skills (`adom-tts` + `adom-tts-build`), and bash-completions. The CLI talks to the shared `service-tts` container — **nothing about a TTS-engine is installed locally.**+That installs the CLI, the `adom-tts` Claude Code skill, and bash completions. The CLI+talks to the shared `service-tts` container — **nothing about a TTS engine is installed+locally.** ## Quick start ```bash-# Hands-free: synthesize and auto-play (the common case). Returns immediately.-adom-tts say "Read me your last answer, I'm driving." --out /tmp/x.mp3 --play+# Speak to the human and VERIFY they heard it (the canonical pattern).+adom-tts say "This is the demo thread — the build is green." \+ --out /tmp/x.mp3 --thread "demo" --desc "build status update" --play --confirm -# Demo voiceover: render a narration track to a file.+# Demo voiceover: render a narration track to a file (no playback, no --thread needed). cat narration.txt | adom-tts say - --out demo-vo.mp3 +# What's playing / queued right now? Did my clip play?+adom-tts status+adom-tts check x.mp3+ # Replay the most recent clip. adom-tts play last ``` -## Screenshots--### Compose, pick a voice, hit Speak-The Playground (`adom-tts serve`) — type what you want to hear, choose any edge-tts voice,-adjust the rate, and synthesize. Every clip is saved to a replayable history.--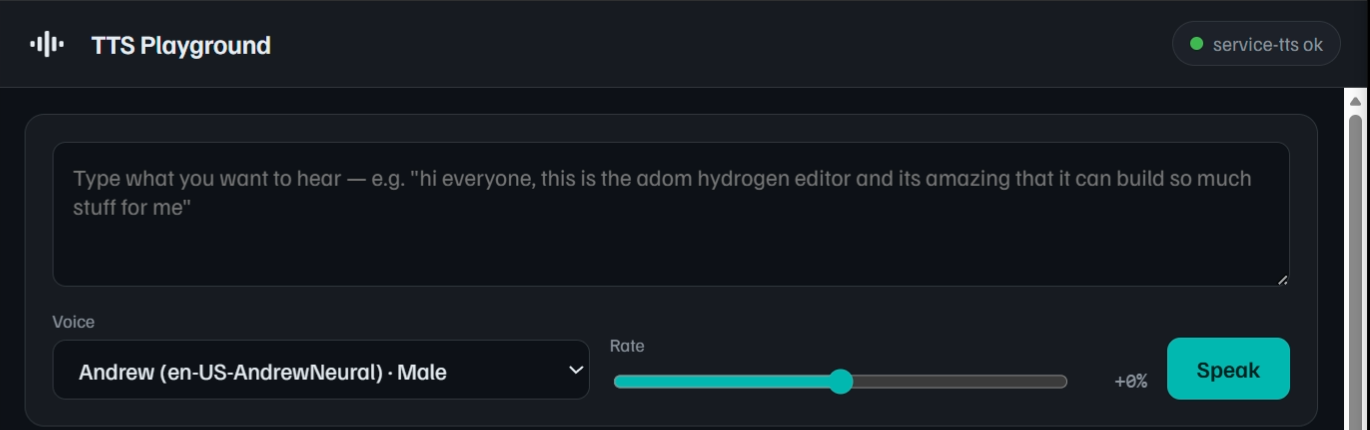--### Pronunciation authoring-Adom terms (`adom-tsci`, `instapcb`, `kicad`) are rewritten server-side before synthesis-from a global override table. Add or preview an override right in the Playground; it-updates the shared `tts-pronunciation` skill so **every** Adom tool benefits.--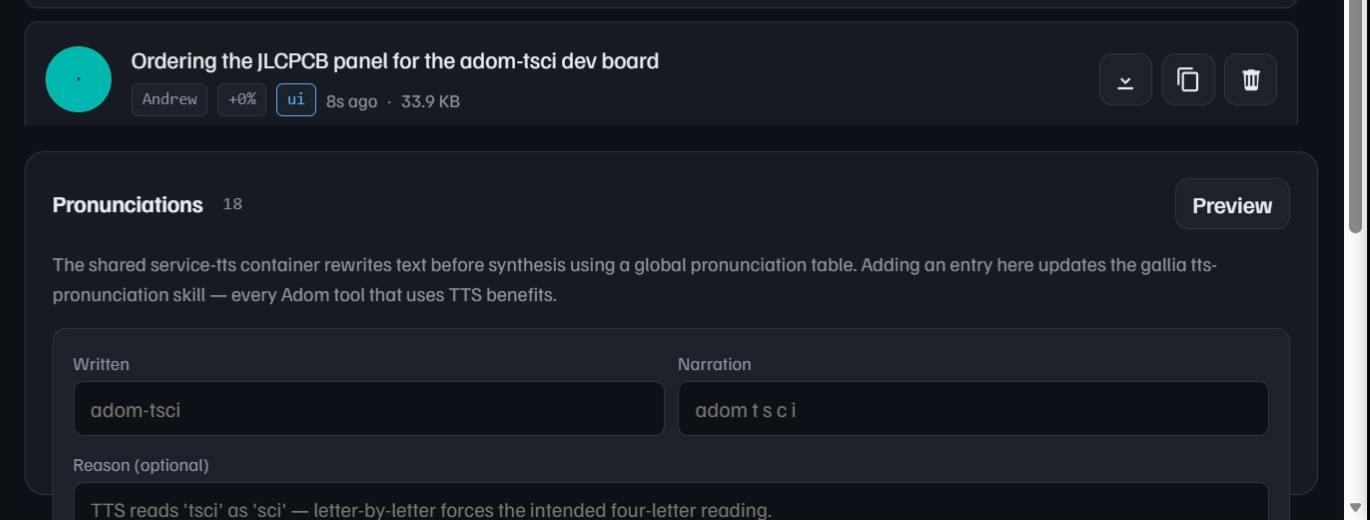- ## Dependencies -This package has **zero `adompkg` dependencies** — it installs and runs standalone.+This package has **zero registry dependencies** — it installs and runs standalone. | Dependency | Required? | Why | |---|---|---|-| `service-tts` container | Runtime (shared) | The actual synthesis backend (edge-tts + pronunciation overrides + cache). It's shared Adom infra — already running, not something you install. The CLI is a thin client over it. |-| `pup` (desktop Chrome) | Optional | Only if you set `--surface pup` to play audio in a desktop browser window instead of the default Hydrogen webview tab. |+| `service-tts` container | Runtime (shared) | The synthesis backend (edge-tts + pronunciation overrides + cache). Shared Adom infra — already running, not something you install. |+| `pup` (desktop Chrome) | Optional | Only for `--surface pup` to play in a desktop browser window instead of the default Hydrogen webview tab. | ## Features -- **Drive mode** — `say --play` / `play last` auto-plays in a Hydrogen webview (or pup- window). One-shot HTTP server + `$VSCODE_PROXY_URI` — no port mappings, no base64 URL- bloat, no custom autoplay HTML. Auto-closes on the audio's `ended` event.-- **Demo voiceover** — house voice `en-US-AndrewNeural`, any edge-tts voice via `--voice`,- speed via `--rate`, stdin piping for long scripts.-- **Server-side pronunciation overrides** — Adom terms come out right without the caller- pre-phoneticizing.-- **Source-hash cache** — repeat renders of the same `(text, voice, rate)` are instant.-- **Swappable backend** — edge-tts today, can move to piper/Azure/ElevenLabs server-side- with zero caller changes.-- **Webview Playground** — compose, voice picker, replayable history, live pronunciation- authoring. Fully AI-drivable (every UI action has an HTTP endpoint).+- **One shared player, many AI threads** — a single persistent server owns one webview;+ clips from every thread play sequentially, never overlapping, each labeled with its+ thread and description.+- **Verified playback** — `--confirm` blocks until the human actually heard the clip;+ `check` answers "did mine play?"; every command returns hints teaching the AI the+ next correct step.+- **Never lose a clip** — buffering while your device is offline (up to 10 min),+ automatic retries, hotspot-proof download-then-play, and the replayable History.+- **Demo voiceover** — house voice `en-US-AndrewNeural`, any edge-tts voice via+ `--voice`, speed via `--rate`, stdin piping for long scripts, source-hash cache.+- **Server-side pronunciation overrides** — Adom terms come out right without the+ caller pre-phoneticizing.+- **Swappable backend** — edge-tts today; can move to piper/Azure/ElevenLabs+ server-side with zero caller changes. ## Talk to the AI @@ -104,66 +130,62 @@ Paste any of these into Claude Code — they use the exact words the skill trigg - "Read that back to me, I can't look at the screen." - "I'm in the car, narrate the answer." +**Listening at your desk**+- "Say it out loud instead of writing it."+- "Talk to me while I work on something else."+ **Make audio / voiceover**-- "Synthesize a 30-second walkthrough of this design and play it for me." - "Render this script as a demo voiceover track."-- "Make audio from this and play it."+- "Synthesize a 30-second walkthrough of this design and play it for me." **Replay**-- "Play the last TTS clip again."--**Configure / teach**-- "Teach the TTS service that aci is pronounced A-C-I."-- "Open the TTS Playground."+- "Play the last TTS clip again." / "Replay the one I missed from the history." -## Skills+## Skills (see the Skills tab) -| Skill | Purpose |-|---|---|-| `adom-tts` | Main skill — drive mode, voiceover, the CLI, the Playground, and the "never install a local TTS engine" guardrail. |-| `adom-tts-build` | Release flow — bump, build, push source + tarball to the wiki, publish. |+| Tier | Skill | Purpose |+|---|---|---|+| User | `adom-tts` | Drive mode, listen-at-your-desk, voiceovers, the verified-playback contract. Ships with every install. |+| Dev | `adom-tts-dev` | The dev cycle + engineering rules for the shared player (source-only). |+| Publish | `adom-tts-publish` | How releases of this app reach the wiki (source-only). | ## CLI reference | Command | Description | |---|---|-| `adom-tts say "<text>" --out f.mp3 [--play]` | Synthesize; `--play` auto-plays it. `-` reads stdin. |-| `adom-tts play last\|<id>\|<path> [--wait]` | Replay a clip (newest, by id/hash, or a file). |+| `adom-tts say "<text>" --out f.mp3 --thread T --desc D [--play --confirm]` | Synthesize; `--play` queues it on the shared player (requires `--thread` + `--desc`); `--confirm` blocks until verified heard. `-` reads stdin. |+| `adom-tts check <clip.mp3>` | Non-blocking: QUEUED / PLAYING / PLAYED / FAILED for your clip. |+| `adom-tts status` | Live player, current clip, the whole queue in order. |+| `adom-tts play last\|<id>\|<path>` | Replay a clip (newest, by id/hash, or a file). |+| `adom-tts control replay\|pause\|play\|toggle` | Drive the live player without reloading it. |+| `adom-tts reopen` | Re-offer the player tab if it was closed (queue survives). |+| `adom-tts logs [--tail N]` | Playback/synthesis event log with verdicts + anomaly hints. | | `adom-tts serve [--port N]` | Open the Playground webview. |-| `adom-tts voices` | List edge-tts voices (JSON). |-| `adom-tts pronunciations` / `pron add` | View / propose pronunciation overrides. |-| `adom-tts health` | Service + edge-tts version. |-| `adom-tts config [--show]` | Which service URL this binary hits (+ play surface). |+| `adom-tts voices` / `pronunciations` / `health` / `config` | Service info. | **Useful flags:** `--voice en-US-AriaNeural`, `--rate +15%`, `--surface pup`, `--no-pronunciations`. `$ADOM_TTS_API` overrides the baked-in service URL. **Exit codes:** `0` ok · `1` invalid input · `2` service unreachable · `4` service-side-error. On a non-zero exit the service is down — report it; **do not** install a local TTS-engine as a workaround.+error · `5` playback not confirmed · `6` missing `--thread`/`--desc` with `--play`.+On `2`/`4` the service is down — report it; **do not** install a local TTS engine as a+workaround. ## Open source — modify it, then publish it back -`adom-tts` is **open source under the MIT license.** Use it, fork it, and modify it to-your heart's content. Better still: the whole project lives on the wiki as a git repo-(see the **Files** tab), so improving it is a first-class workflow, not an afterthought:--1. **Get the source** — `adompkg install adom-tts`, or browse/clone it from the Files tab.-2. **Change whatever you want** — add a voice, a flag, a play surface; fix a bug; sharpen- the docs.-3. **Publish it back for everyone** — `adompkg version patch && adompkg publish`. Your- improvement goes straight back to the wiki registry, and **the entire Adom community- inherits it** the next time they install `adom-tts`.+`adom-tts` is **open source under the MIT license** (see `LICENSE`). The whole project+lives on this page as a git repo (see the **Files** tab): -That's the whole idea: the wiki is the shared registry, so a fix you make once benefits-everyone. Don't sit on a good change locally — ship it back.+1. **Get the source** — `adom-wiki repo clone adom/adom-tts`.+2. **Change whatever you want** — add a voice, a flag, a play surface; fix a bug.+3. **Publish it back** — bump the version, `adom-wiki pkg publish`, `adom-wiki repo push`.+ Your improvement goes to the shared registry and the whole community inherits it. ### One part isn't yours to change: the voice backend -The MIT grant covers this CLI and the Playground. It does **not** cover the synthesis-backend. Every `adom-tts say` call hits **Adom's cloud `service-tts` API**, which runs on-Adom's infrastructure and counts against **Adom's quota**. That backend is an **Adom-service, subject to change** — its endpoints, voices, rate limits, pricing, and-availability can be modified or retired at Adom's discretion. Your fork is free and yours;-the shared voice service it calls is a managed Adom service, not part of the open-source-guarantee.+The MIT grant covers this CLI and the player. It does **not** cover the synthesis+backend. Every `adom-tts say` call hits **Adom's cloud `service-tts` API**, which runs+on Adom's infrastructure and counts against **Adom's quota**. That backend is an Adom+service, subject to change — endpoints, voices, rate limits, and availability can be+modified or retired at Adom's discretion. Your fork is free and yours; the shared voice+service it calls is a managed Adom service, not part of the open-source guarantee.
VERSION+1−1@@ -1 +1 @@-1.9.16+1.9.17
bin/adom-tts⋯ 1 unchanged line ⋯
package.json+1−1@@ -1,6 +1,6 @@ { "slug": "adom-tts",- "version": "1.9.16",+ "version": "1.9.17", "type": "app", "description": "Adom's shared text-to-speech CLI + Playground. Reads your AI answers back to you while driving, and renders perfectly-timed voiceover tracks for demo videos.", "license": "MIT",
page.json+14−1@@ -4,7 +4,7 @@ "slug": "adom-tts", "title": "Adom TTS — Text to Speech", "brief": "Adom's shared voice service. Reads your AI's answers back to you while you drive, and renders perfectly-timed voiceover tracks for your demo videos — so you never record your own voice.",- "version": "1.9.16",+ "version": "1.9.17", "license": "MIT", "tags": [ "tts",@@ -12,6 +12,7 @@ "audio", "demo", "accessibility",+ "cli", "open-source", "mit" ],@@ -64,5 +65,17 @@ ], "install": { "binary_name": "adom-tts"+ },+ "description": "Adom's shared text-to-speech CLI + Playground. Reads your AI answers back to you while driving, and renders perfectly-timed voiceover tracks for demo videos.",+ "dependencies": {},+ "scripts": {+ "install": "./install.sh",+ "uninstall": "./uninstall.sh"+ },+ "needs_sudo": false,+ "org": "adom",+ "author": {+ "name": "John Lauer",+ "email": "[email protected]" } }
screenshots/cli-verified.pngadded⋯ 1 unchanged line ⋯
screenshots/history-drawer.pngadded⋯ 1 unchanged line ⋯
screenshots/player-live.pngadded⋯ 1 unchanged line ⋯