app
Adom TTS: Text to Speech
Public Made by Adomby adom
Adom's shared voice service. Reads your AI's answers back to you while you drive, and renders perfectly-timed voiceover tracks for your demo videos, so you never record your own voice.
← Commit history
Open-source release: source + README + hero + skills (v0.2.0)
5 files changed
+280−89
.gitignoreadded+3@@ -0,0 +1,3 @@+target/+Cargo.lock+*.swp
BUILD-SKILL.mdadded+94@@ -0,0 +1,94 @@+---+name: adom-tts-build+description: Build and release a new version of adom-tts. Use when the user says "release adom-tts", "publish adom-tts", "cut a new adom-tts version", "bump adom-tts", "ship adom-tts", or "push adom-tts to the wiki".+---++# Release adom-tts++A release syncs four places to the same version X.Y.Z:+`VERSION`, `Cargo.toml`, `adom-tts --version`, wiki page `pub_version` (top-level `version:` field on the wiki publish).++## Steps++1. **Bump** — decide X.Y.Z (semver). Then:+ ```bash+ echo "X.Y.Z" > VERSION+ sed -i 's/^version = .*/version = "X.Y.Z"/' Cargo.toml+ ```++2. **Local build + smoke test**:+ ```bash+ cargo build --release+ ./target/release/adom-tts --version # must print "adom-tts X.Y.Z"+ ./target/release/adom-tts health # service-tts reachable+ ./target/release/adom-tts say "hi" --out /tmp/hi.mp3+ ./target/release/adom-tts pron list | jq '.count'+ ```++3. **Icon audit** (brand rule §1b, gate every release):+ ```bash+ grep -nE 'fill="(#00b8b0|#00d4cb)"|stroke="(#00b8b0|#00d4cb)"' \+ docs/icon.svg src/ui.html 2>/dev/null+ # must return zero matches+ grep -oE 'fill="#[0-9a-fA-F]{3,8}"|stroke="#[0-9a-fA-F]{3,8}"' docs/icon.svg | \+ grep -v -E '"#e6edf3"|"#ffffff"|"#fff"|"#0d1117"|"none"|"transparent"|"currentColor"' \+ && { echo "NON-WHITELISTED ICON FILL — release blocked"; exit 1; } || echo "(icon.svg clean)"+ ```++4. **Drive the UI** (per app-creator — show the user a screenshot before publish):+ ```bash+ ./target/release/adom-tts serve --port 8795 &+ sleep 2+ adom-cli hydrogen webview refresh --name "TTS Playground"+ adom-cli hydrogen screenshot panel --name "TTS Playground"+ curl -sS http://127.0.0.1:8795/state | jq .+ curl -sS http://127.0.0.1:8795/console | jq '.entries | length' # must be 0+ ```+ Wait for explicit user approval before continuing.++5. **Commit + push source**:+ ```bash+ git add -A+ git commit -m "Release X.Y.Z — <changelog line>"+ git tag vX.Y.Z+ git push origin main --tags+ ```++6. **Upload the binary to the wiki** (auto-replaces the prior docker_binary):+ ```bash+ adom-wiki asset upload apps/adom-tts \+ --asset-type docker_binary \+ --file target/release/adom-tts \+ --caption "vX.Y.Z build for adom docker"+ curl -I https://wiki-ufypy5dpx93o.adom.cloud/static/apps/adom-tts/adom-tts+ # must be HTTP/1.1 200 OK, content-type: application/octet-stream+ ```++7. **Publish the wiki page** (delete + recreate because metadata updates through the v1 PATCH endpoint are unreliable; see tool-publisher "Updating a Published Tool"):+ ```bash+ WIKI=https://wiki-ufypy5dpx93o.adom.cloud+ adom-wiki page delete apps/adom-tts+ adom-wiki page publish --body-file /tmp/adom-tts-wiki.json # includes "version": "X.Y.Z"+ adom-wiki page get apps/adom-tts | jq '.page.pub_version'+ ```++8. **Confirm end-to-end** on a fresh shell:+ ```bash+ curl -fsSL $WIKI/static/apps/adom-tts/adom-tts -o /tmp/adom-tts-fresh \+ && chmod +x /tmp/adom-tts-fresh+ /tmp/adom-tts-fresh --version # → adom-tts X.Y.Z+ /tmp/adom-tts-fresh health # service reachable+ ```++## Pre-release checklist++- [ ] `VERSION`, `Cargo.toml`, `adom-tts --version`, wiki `pub_version` all return X.Y.Z+- [ ] Icon audit grep returns zero hits+- [ ] User has seen a screenshot of the running playground+- [ ] `GET /console` shows no errors after a UI smoke run+- [ ] `apps/adom-tts` install_hint is the curl-based one-liner (no `gh release download`)+- [ ] Fresh-container curl install works without GitHub credentials++## Service-tts coupling++`adom-tts` is a client — the server is `service-tts`. If you bump `adom-tts` only, the service keeps running the prior version. If you need new server behavior (new endpoint, new pronunciation apply logic), cut a `service-tts` release too — see its `BUILD-SKILL.md`.
README.md+115−76@@ -1,110 +1,149 @@ # adom-tts -Thin Rust CLI + webview playground for [service-tts](/apps/service-tts) — Adom's shared edge-tts wrapper with pronunciation overrides + source-hash cache.+**Adom's shared voice.** A thin Rust CLI + webview Playground for `service-tts` — the+edge-tts wrapper with Adom pronunciation overrides and a source-hash cache. It does two+things that matter day to day: -## What's new in 0.1.2 — built-in auto-player+- 🚗 **When you're driving** — it reads your AI's answers back to you, hands-free.+- 🎬 **When you're making a demo** — it renders the video's voiceover track with exact+ timing, so you never have to record your own voice. -The CLI now plays its own mp3s. **Stop authoring custom autoplay HTML or `python3 -m http.server` workarounds.**+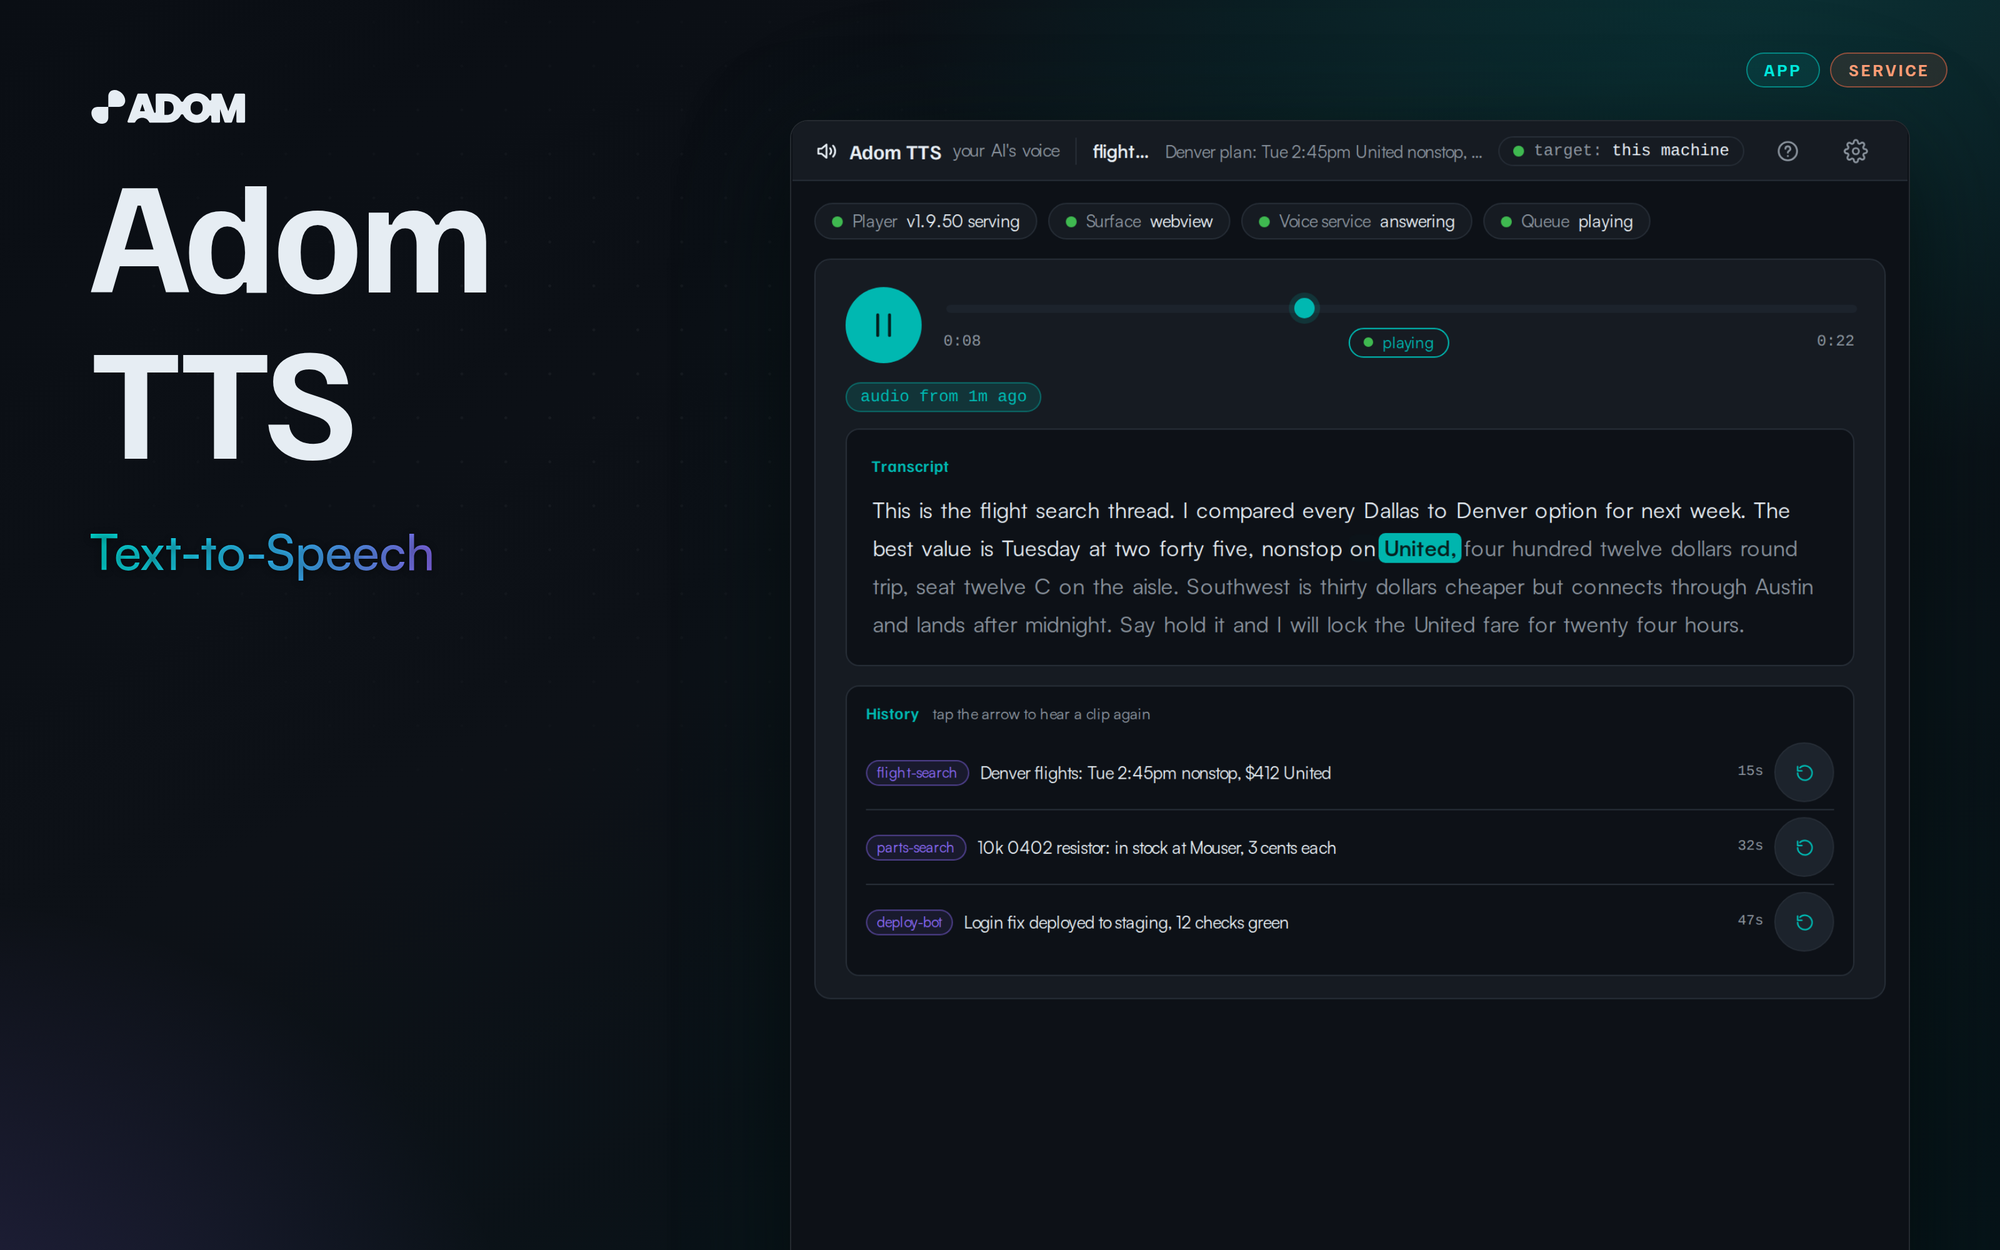 -```bash-# One shot: synthesize and auto-play. CLI returns immediately (detached).-adom-tts say "Read me your latest answer, I'm driving." --out /tmp/x.mp3 --play+--- -# Replay the newest history clip.-adom-tts play last+## The two use cases -# Replay any history clip by full id or unique substring of its hash.-adom-tts play 5f79f0-```+### 🚗 Drive mode (hands-free) -**How it works.** `play` (and `say --play`) spins up a one-shot tiny_http server bound to a 127.0.0.1 ephemeral port, serving the mp3 + a small autoplay page. The container's `$VSCODE_PROXY_URI` wraps the port into a Cloudflare-routable URL. The chosen surface — Hydrogen webview tab (default) or pup browser window — navigates to that URL. Same plumbing both surfaces, no port mappings, no clip-size limits, no base64 URL bloat.+You're in the car. You can't read the screen. Just say it: -**Tab/window auto-closes** when the audio's `ended` event fires (or a 5-min cap). Programmatic, not AI-driven — the binary handles cleanup. Override with `ADOM_TTS_KEEP_OPEN=1` if you want the player to linger.+> "Read me your last answer, I'm driving." -**Surface precedence:** `--surface hydrogen|pup` flag → `$ADOM_TTS_SURFACE` env → `~/.adom/tts/config.toml` (`[play] surface = "..."`) → `"hydrogen"` default.+Claude composes the reply, pipes it through `adom-tts say --play`, and it plays aloud —+no screen, no typing. The skill triggers on the words you'd actually use ("read it to+me", "read that back", "I'm in the car", "narrate the answer", and many more). -**Self-teaching hints.** `say` without `--play` emits stderr hints pointing the AI at the auto-player and warning against the anti-patterns we've seen sessions fall into (custom HTML, port-add, etc.). Silenceable via `ADOM_TTS_NO_HINTS=1`.+### 🎬 Demo voiceover (exact timing) -## Hands-free trigger phrases+Writing a walkthrough or product demo? Feed `adom-tts` your narration script and get a+clean, perfectly-timed `.mp3` voiceover track in the house voice (`en-US-AndrewNeural`).+No recording booth, no retakes, no listening to your own voice. Because every clip is+cached by source hash, iterating on the script is instant after the first render — which+is why `demo-recording`, `video-post`, and every tour/walkthrough tool route through it. -When the user says "I'm driving", "read it to me", "can't read the screen", "in the car", "narrate the answer" — they CANNOT see your text response. Synthesize and `--play`. The skill front-matter lists the full trigger catalog.+--- -## Playground webview (unchanged from 0.1.1)+## Install -`adom-tts serve` opens a Hydrogen webview panel. Type what you want to hear, pick a voice, hit Enter. Every clip you generate (or that any other tool drops via `adom-tts say --history` / `adom-tts push`) is saved to `~/.adom/tts/history/` and replayable from the list. Download, copy shareable URLs, delete — all per-clip.+```bash+adompkg install adom-tts+adom-tts health # confirm the shared voice service is reachable+``` -**Pronunciation authoring.** A live view of the global pronunciation table sits next to the compose area. When your input contains a term that already has an override, a hint appears: "*adom-tsci* will be voiced as `adom t s c i` · global override". An Add form lets you propose new entries, with a **Preview** button that synthesizes raw + phoneticized forms back-to-back, and a **Propose** button that writes straight into `gallia/skills/tts-pronunciation/pronunciations.json`.+That installs the CLI, the Claude Code skills (`adom-tts` + `adom-tts-build`), and bash+completions. The CLI talks to the shared `service-tts` container — **nothing about a TTS+engine is installed locally.** -**Everything is AI-drivable.** Every UI action has an HTTP equivalent — `POST /synth`, `GET /history`, `DELETE /history/:id`, `GET /pronunciations`, `POST /pronunciation/propose`, `GET /state`, `GET /console`, `POST /shutdown`.+## Quick start -## Install (Tier B)+```bash+# Hands-free: synthesize and auto-play (the common case). Returns immediately.+adom-tts say "Read me your last answer, I'm driving." --out /tmp/x.mp3 --play -Paste-into-Claude:+# Demo voiceover: render a narration track to a file.+cat narration.txt | adom-tts say - --out demo-vo.mp3 -```bash-curl -fsSL https://wiki-ufypy5dpx93o.adom.cloud/static/apps/adom-tts/adom-tts \- -o /tmp/adom-tts && chmod +x /tmp/adom-tts \- && sudo install -m 0755 /tmp/adom-tts /usr/local/bin/adom-tts \- && adom-tts install \- && adom-tts health+# Replay the most recent clip.+adom-tts play last ``` -`adom-tts install` deploys the SKILL.md + `adom-tts-build` sibling skill + bash completions. Gallia's 30-min refresh hook keeps the installed version in sync with the wiki's `pub_version`.+## Screenshots -## CLI+### Compose, pick a voice, hit Speak+The Playground (`adom-tts serve`) — type what you want to hear, choose any edge-tts voice,+adjust the rate, and synthesize. Every clip is saved to a replayable history. -```bash-# Synthesis + auto-play (the common case)-adom-tts say "Hello from adom-tsci" --out hello.mp3 --play-adom-tts say "narration" --out n.mp3 --voice en-US-AriaNeural --play+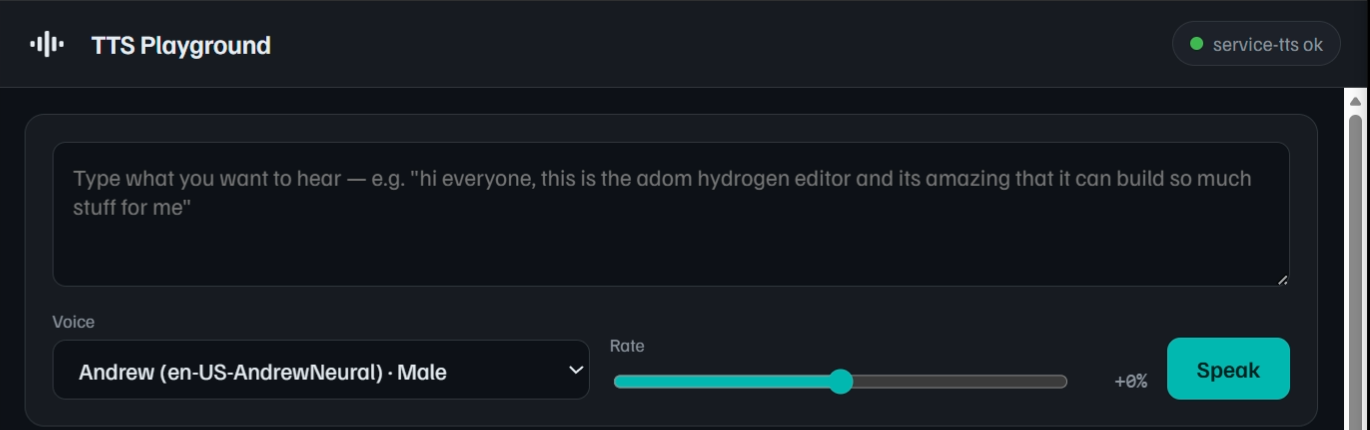 -# Replay-adom-tts play last-adom-tts play /tmp/x.mp3 --wait # block until ended (max 5 min)-adom-tts play /tmp/x.mp3 --surface pup--# Synthesis only (rare — when you genuinely just need the file)-adom-tts say "for later" --out later.mp3--# Playground-adom-tts serve [--port 8795]-adom-tts push path/to/clip.mp3--# Pronunciations-adom-tts pron list-adom-tts pron add "adom-tsci" "adom t s c i" --reason "letter-by-letter forces 4-letter reading"--# Introspection-adom-tts voices | jq '.count'-adom-tts pronunciations | jq '.count'-adom-tts health-adom-tts config # current service URL + bake/env source-adom-tts config --show # also dump resolved play surface + config path-```+### Pronunciation authoring+Adom terms (`adom-tsci`, `instapcb`, `kicad`) are rewritten server-side before synthesis+from a global override table. Add or preview an override right in the Playground; it+updates the shared `tts-pronunciation` skill so **every** Adom tool benefits.++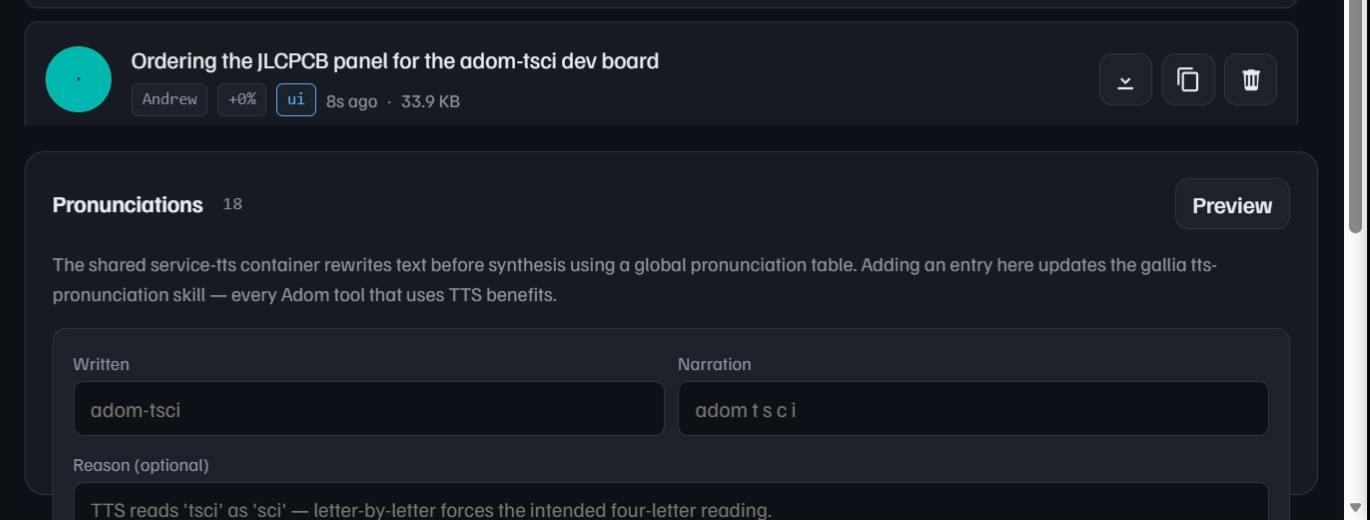 -`$ADOM_TTS_API` overrides the baked-in service URL. Default voice is `en-US-AndrewNeural` — the house voice for every Adom demo.+## Dependencies -## Anti-patterns the new auto-player exists to prevent+This package has **zero `adompkg` dependencies** — it installs and runs standalone. -- ❌ `python3 -m http.server <port>` to serve the mp3. Pup runs on the user's *desktop*; container localhost is unreachable. Hydrogen webviews have the same constraint.-- ❌ Custom HTML with base64-inlined mp3 + `data:` URL. Past 2 MB this hits Chrome's URL length limit.-- ❌ `adom-cli carbon containers port-add` for a permanent `*.adom.cloud` subdomain. Total overkill for a one-shot.-- ✅ Just use `--play`. The binary handles surface, URL, autoplay, and cleanup.+| Dependency | Required? | Why |+|---|---|---|+| `service-tts` container | Runtime (shared) | The actual synthesis backend (edge-tts + pronunciation overrides + cache). It's shared Adom infra — already running, not something you install. The CLI is a thin client over it. |+| `pup` (desktop Chrome) | Optional | Only if you set `--surface pup` to play audio in a desktop browser window instead of the default Hydrogen webview tab. | -## Who uses this+## Features -- `demo-recording` / `voiceover` / `tour` — everyone that renders narration-- `aci voice` — backend precedence `$ACI_VOICE_API → adom-tts CLI → edge-tts local fallback`-- Drive-mode users via Claude RC — synthesize + auto-play means hands-free answers-- Any new tool that needs spoken output should shell out to `adom-tts say` rather than calling edge-tts directly+- **Drive mode** — `say --play` / `play last` auto-plays in a Hydrogen webview (or pup+ window). One-shot HTTP server + `$VSCODE_PROXY_URI` — no port mappings, no base64 URL+ bloat, no custom autoplay HTML. Auto-closes on the audio's `ended` event.+- **Demo voiceover** — house voice `en-US-AndrewNeural`, any edge-tts voice via `--voice`,+ speed via `--rate`, stdin piping for long scripts.+- **Server-side pronunciation overrides** — Adom terms come out right without the caller+ pre-phoneticizing.+- **Source-hash cache** — repeat renders of the same `(text, voice, rate)` are instant.+- **Swappable backend** — edge-tts today, can move to piper/Azure/ElevenLabs server-side+ with zero caller changes.+- **Webview Playground** — compose, voice picker, replayable history, live pronunciation+ authoring. Fully AI-drivable (every UI action has an HTTP endpoint). -## Exit codes+## Talk to the AI -| code | meaning |+Paste any of these into Claude Code — they use the exact words the skill triggers on:++**Hands-free / drive mode**+- "I'm driving — read me your last answer."+- "Read that back to me, I can't look at the screen."+- "I'm in the car, narrate the answer."++**Make audio / voiceover**+- "Synthesize a 30-second walkthrough of this design and play it for me."+- "Render this script as a demo voiceover track."+- "Make audio from this and play it."++**Replay**+- "Play the last TTS clip again."++**Configure / teach**+- "Teach the TTS service that aci is pronounced A-C-I."+- "Open the TTS Playground."++## Skills++| Skill | Purpose | |---|---|-| `0` | ok |-| `1` | invalid input (empty text, missing `--out`) |-| `2` | service unreachable — check `adom-tts config` or set `$ADOM_TTS_API` |-| `4` | service-side error (edge-tts failed, etc.) |+| `adom-tts` | Main skill — drive mode, voiceover, the CLI, the Playground, and the "never install a local TTS engine" guardrail. |+| `adom-tts-build` | Release flow — bump, build, push source + tarball to the wiki, publish. |++## CLI reference++| Command | Description |+|---|---|+| `adom-tts say "<text>" --out f.mp3 [--play]` | Synthesize; `--play` auto-plays it. `-` reads stdin. |+| `adom-tts play last\|<id>\|<path> [--wait]` | Replay a clip (newest, by id/hash, or a file). |+| `adom-tts serve [--port N]` | Open the Playground webview. |+| `adom-tts voices` | List edge-tts voices (JSON). |+| `adom-tts pronunciations` / `pron add` | View / propose pronunciation overrides. |+| `adom-tts health` | Service + edge-tts version. |+| `adom-tts config [--show]` | Which service URL this binary hits (+ play surface). |++**Useful flags:** `--voice en-US-AriaNeural`, `--rate +15%`, `--surface pup`,+`--no-pronunciations`. `$ADOM_TTS_API` overrides the baked-in service URL.++**Exit codes:** `0` ok · `1` invalid input · `2` service unreachable · `4` service-side+error. On a non-zero exit the service is down — report it; **do not** install a local TTS+engine as a workaround.++## License -Source (private): [`adom-inc/adom-tts`](https://github.com/adom-inc/adom-tts). Service backend: [service-tts](/apps/service-tts). Pronunciation source of truth: `gallia/skills/tts-pronunciation/pronunciations.json`.+MIT. Source is open and lives on this wiki page (Files tab) — browse, fork, or send a PR.
build.rsadded+34@@ -0,0 +1,34 @@+//! Bake the production service-tts URL into the binary at compile time.+//!+//! Precedence:+//! 1. $SERVICE_TTS_URL (set by wiki-publish / release CI)+//! 2. `url` field scraped from ../service-tts/service.json (dev)+//! 3. Local dev fallback http://127.0.0.1:8783++use std::{fs, path::PathBuf};++fn main() {+ println!("cargo:rerun-if-env-changed=SERVICE_TTS_URL");+ println!("cargo:rerun-if-changed=../service-tts/service.json");+ let url = std::env::var("SERVICE_TTS_URL")+ .or_else(|_| read_url_from_service_json())+ .unwrap_or_else(|_| "http://127.0.0.1:8783".to_string());+ println!("cargo:rustc-env=SERVICE_TTS_URL={}", url);+}++fn read_url_from_service_json() -> Result<String, std::io::Error> {+ let manifest = PathBuf::from(env!("CARGO_MANIFEST_DIR"));+ let svc_json = manifest.parent()+ .map(|p| p.join("service-tts").join("service.json"))+ .ok_or_else(|| std::io::Error::new(std::io::ErrorKind::NotFound, "sibling"))?;+ let svc_json = svc_json.canonicalize()?;+ let contents = fs::read_to_string(&svc_json)?;+ for line in contents.lines() {+ if let Some(rest) = line.split_once("\"url\"") {+ if let Some(v) = rest.1.split('"').nth(1) {+ return Ok(v.to_string());+ }+ }+ }+ Err(std::io::Error::new(std::io::ErrorKind::NotFound, "no url in service.json"))+}
install.sh+34−13@@ -1,15 +1,36 @@ #!/bin/bash-set -e-PKG_DIR="$(cd "$(dirname "$0")" && pwd)"-SKILLS_DIR="$HOME/.claude/skills"-mkdir -p "$SKILLS_DIR/adom-tts"-if [ -f "$PKG_DIR/SKILL.md" ]; then- cp "$PKG_DIR/SKILL.md" "$SKILLS_DIR/adom-tts/SKILL.md"-fi-for skill_dir in "$PKG_DIR/skills"/*/; do- [ -d "$skill_dir" ] || continue- skill_name=$(basename "$skill_dir")- mkdir -p "$SKILLS_DIR/$skill_name"- cp -r "$skill_dir"* "$SKILLS_DIR/$skill_name/"+# install.sh for adom-tts (app).+# Runs from the extracted module directory (~/project/adom_modules/adom-tts/).+set -euo pipefail++DIR="$(cd "$(dirname "$0")" && pwd)"+cd "$DIR"++# 1) Binary onto PATH.+BIN_DIR="${HOME}/.local/bin"+mkdir -p "$BIN_DIR"+install -m 0755 "$DIR/bin/adom-tts" "$BIN_DIR/adom-tts"+echo "Installed adom-tts -> $BIN_DIR/adom-tts"++# 2) Claude Code skills (main + build sibling).+SKILL_DIR="${HOME}/.claude/skills"+for s in adom-tts adom-tts-build; do+ if [ -f "$DIR/skills/$s/SKILL.md" ]; then+ mkdir -p "$SKILL_DIR/$s"+ install -m 0644 "$DIR/skills/$s/SKILL.md" "$SKILL_DIR/$s/SKILL.md"+ echo "Installed skill -> $SKILL_DIR/$s/SKILL.md"+ fi done-echo "Installed adom-tts"++# 3) Bash completion (best-effort, non-fatal).+if [ -f "$DIR/completions/adom-tts.bash" ]; then+ COMP_DIR="${HOME}/.bash_completion.d"+ mkdir -p "$COMP_DIR"+ install -m 0644 "$DIR/completions/adom-tts.bash" "$COMP_DIR/adom-tts" || true+fi++echo+echo "adom-tts installed. Verify the shared voice service is reachable:"+echo " adom-tts health"+echo "Then try drive mode:"+echo " adom-tts say \"Read me your last answer, I'm driving.\" --out /tmp/x.mp3 --play"