skill
adom-plan — Exhaustive Plan Review
Public Made by Adomby adom
Expand a sketch into a full plan, then stress-test it with 6+ adversarial debate agents (Opus vs Sonnet pairs) plus a red-team consensus attack and a scored synthesis.
← Commit history
Publish adom-plan source + README
5 files changed
+631−20
README.md+19−15@@ -1,31 +1,42 @@ # adom-plan — Exhaustive Plan Review -End-to-end planning pipeline: expand a sketch into a detailed plan, then stress-test it via adversarial multi-model debate. Uses **ultraplan** when available (harness-level deep expansion), otherwise runs a built-in Opus expansion pass. Then launches **three adversarial pairs** (6 agents: Opus vs Sonnet per category) arguing architecture, implementation, and security from opposite dispositions. A 7th agent red-teams the consensus. Final output is a scored, vetted plan with validation strategies, E2E testing, risk register, and prioritized action items.+End-to-end planning pipeline: expand a sketch into a detailed plan, then stress-test it via adversarial multi-model debate. Runs a built-in Opus expansion pass to flesh out the sketch, then launches **three adversarial pairs** (6 agents: Opus vs Sonnet per category) arguing architecture, implementation, and security from opposite dispositions. A 7th agent red-teams the consensus. Final output is a scored, vetted plan with validation strategies, E2E testing, a risk register, and prioritized action items. **Total agents: up to 8** (1 expansion + 6 debate + 1 red-team consensus). +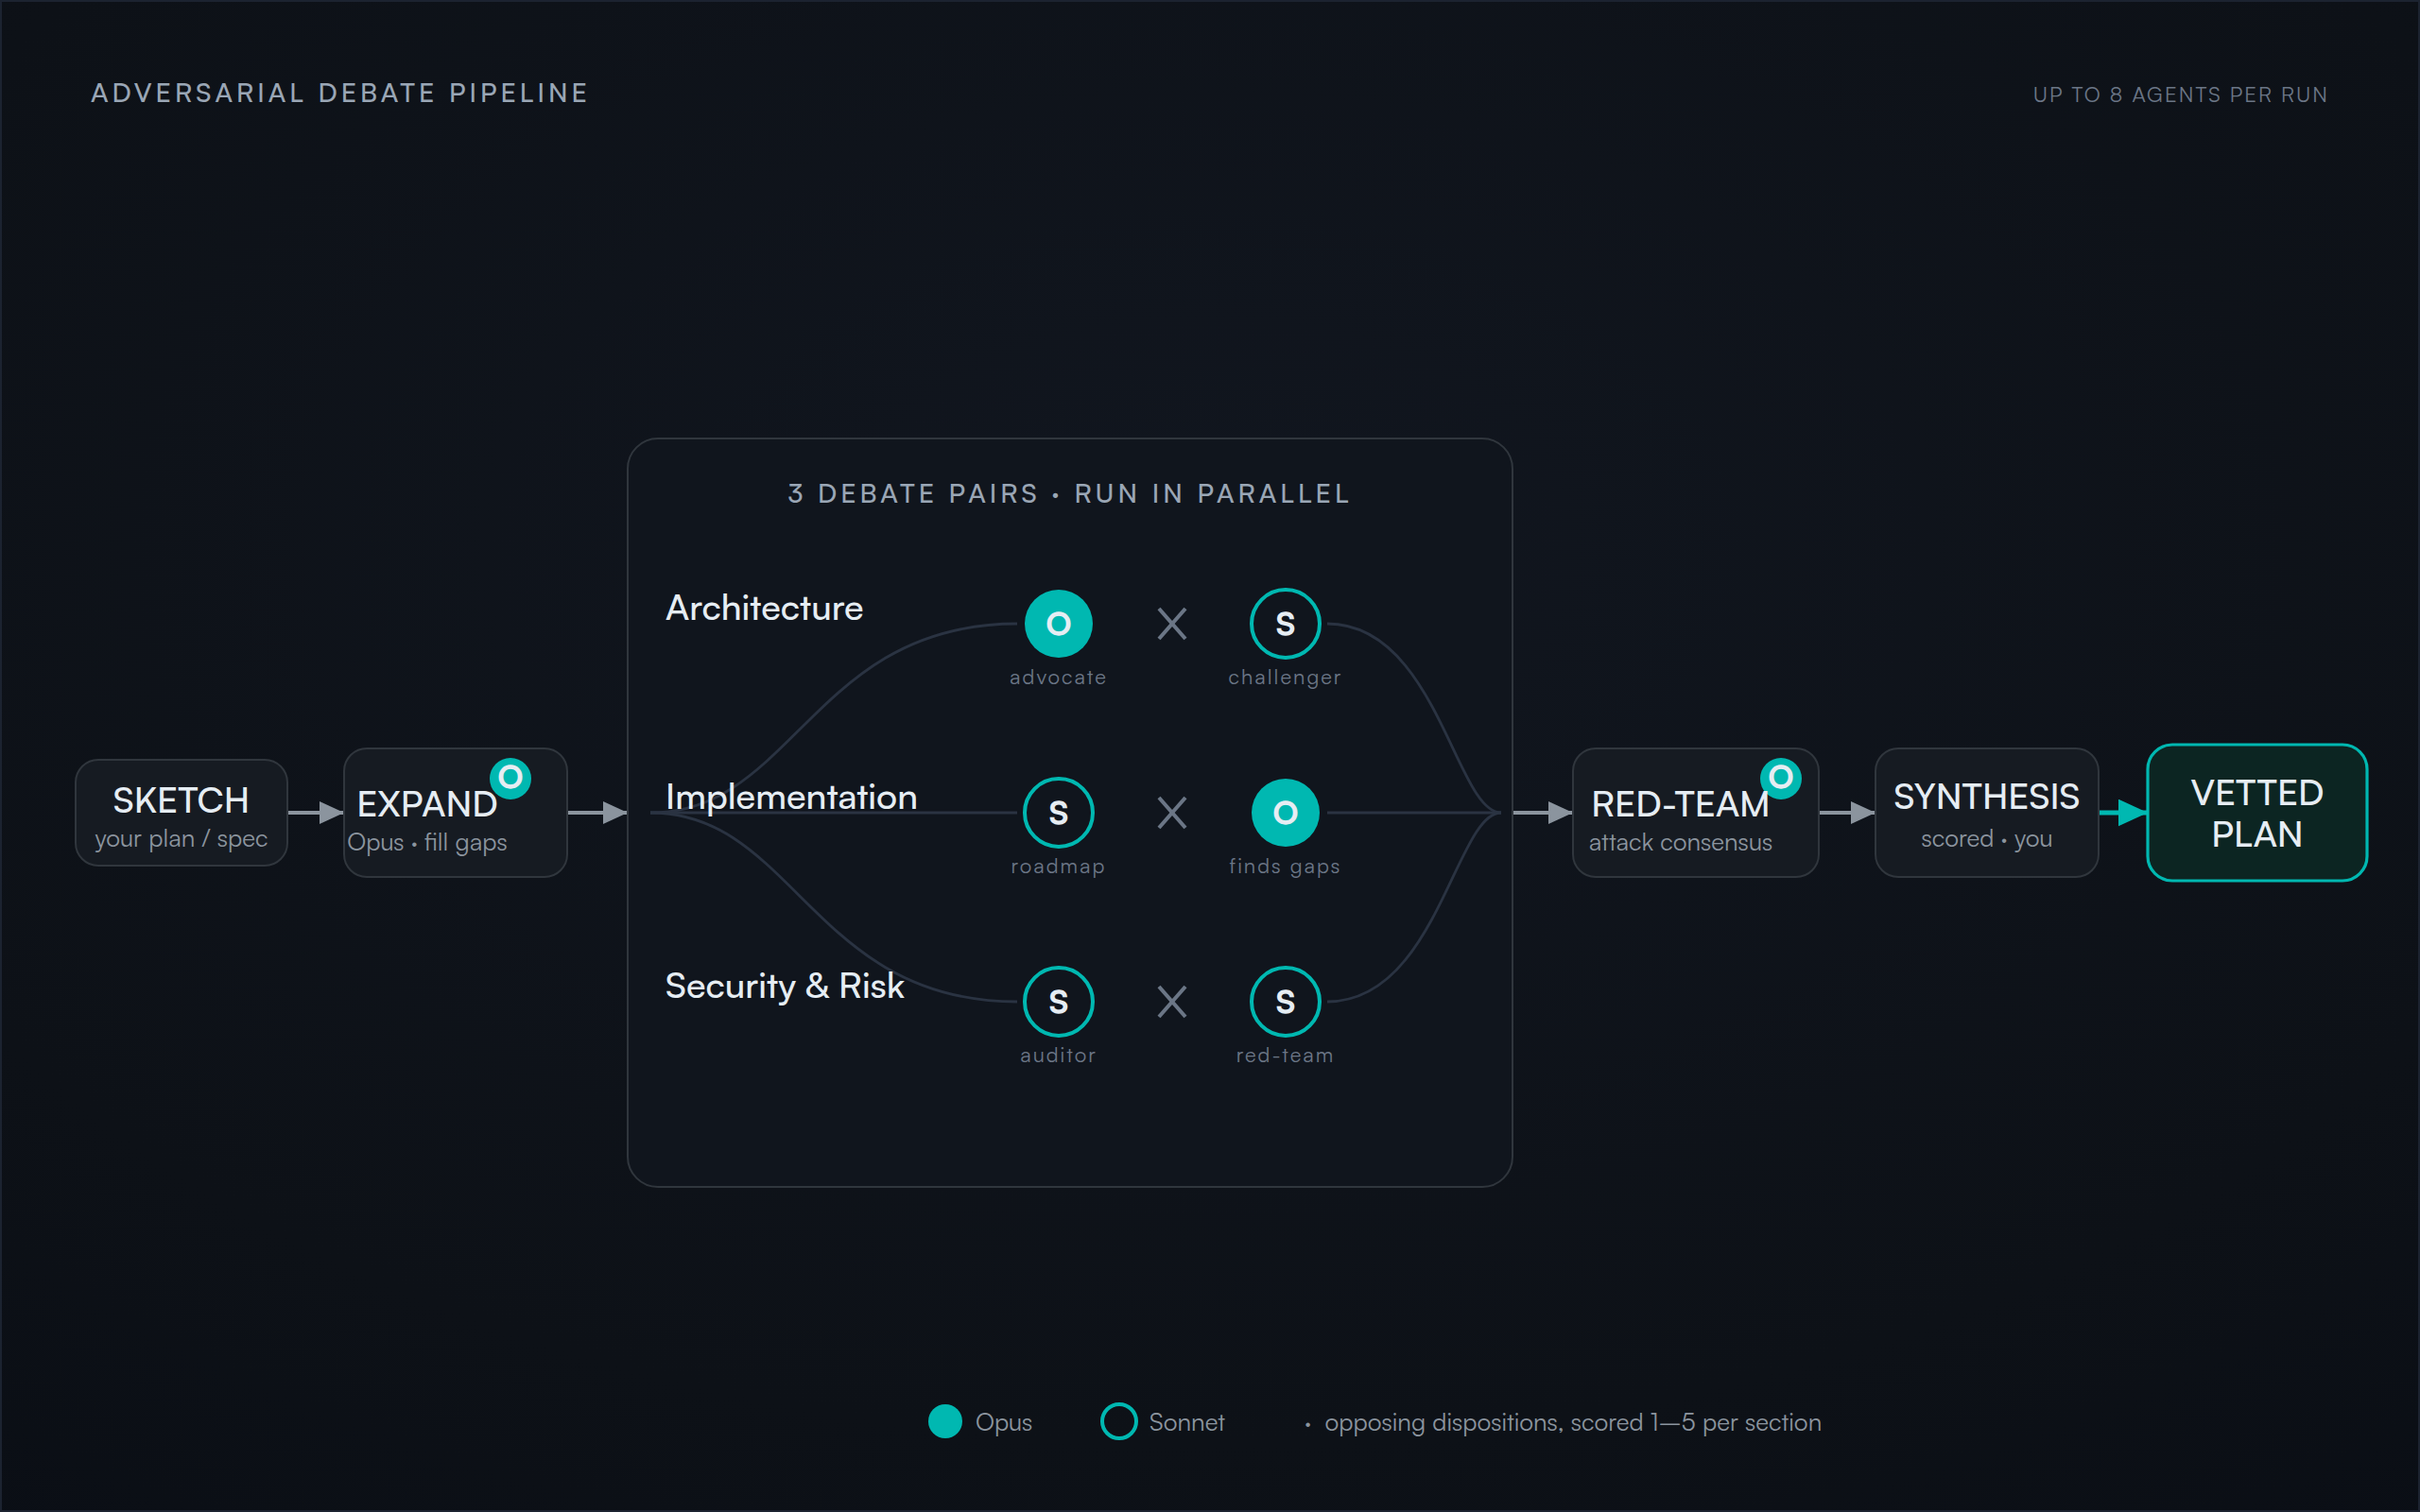+ ## How it works 1. **Phase 0** — Locate the plan (plan file, file path argument, or conversation context)-2. **Phase 0.5** — Expand the plan via ultraplan (if available) or built-in Opus expansion agent+2. **Phase 0.5** — Expand the plan via a built-in Opus expansion agent 3. **Phase 1** — Fetch platform context (wiki catalog, installed skills, recent commits, existing plans) 4. **Phase 2** — Launch 6 adversarial debate agents in parallel (3 pairs): - Architecture: Opus advocate vs Sonnet challenger- - Implementation: Sonnet optimist vs Opus pessimist- - Security: Sonnet auditor vs Sonnet red-team attacker+ - Implementation: Sonnet roadmap-builder vs Opus gap-finder+ - Security & Risk: Sonnet auditor vs Sonnet red-team attacker 5. **Phase 3** — Red-team the consensus with one final Opus agent-6. **Phase 4** — Scored synthesis with scorecard, contested decisions, risk register, E2E strategy, and action items-7. **Phase 5** — Present summary to user+6. **Phase 4** — Scored synthesis: scorecard, contested decisions, risk register, E2E strategy, action items+7. **Phase 5** — Present the summary to the user ## Key features - **Adversarial pairing** — two agents argue each category from opposite dispositions, surfacing disagreements a single model would self-censor - **Multi-model diversity** — Opus reasons conservatively and architecturally; Sonnet is pragmatic and detail-oriented-- **Structured scoring** — 1-5 scale across Feasibility, Maintainability, Platform Leverage, Simplicity; 2+ point deltas auto-flagged-- **Platform awareness** — fetches wiki catalog so agents reference real tools, not hypothetical ones+- **Structured scoring** — 1–5 scale across Feasibility, Maintainability, Platform Leverage, Simplicity; 2+ point deltas auto-flagged+- **Platform awareness** — fetches the wiki catalog so agents reference real tools, not hypothetical ones - **The 30-Day Failure Scenario** — forces concrete, actionable thinking about what will actually go wrong - **Consensus red-team** — attacks the "safe" decisions everyone agrees on, because the most dangerous risks are the ones nobody flags +## Then build it — pairs with `three-musketeers`++adom-plan is the **plan half** of Adom's complex-project pipeline. Once the plan is vetted here, build it with **[`three-musketeers`](/adom/three-musketeers)** — the companion skill that drives the actual build through a Builder → Adversarial Reviewer → Verifier loop until it genuinely works:++1. **Plan robustly** with adom-plan — 6+ vetting agents harden *what to build*.+2. **Build robustly** with three-musketeers — 3 building agents harden *that it was built and actually works* (the Verifier confirms behavior as a user, not against the plan, so the builder is free to correct anything adom-plan got wrong).++Expensive but effective — reach for the full plan→build pipeline on high-stakes or long-running work.+ ## Invocation ```@@ -33,13 +44,6 @@ End-to-end planning pipeline: expand a sketch into a detailed plan, then stress- /adom-plan path/to/plan.md # review a specific file ``` -## Installation--Bundled with gallia. Available at `~/.claude/skills/adom-plan/` after `install.mjs` runs. The skill consists of two files:--- `SKILL.md` (212 lines) — workflow, phases, synthesis format, guidelines-- `debate-prompts.md` (413 lines) — all 8 agent prompt templates (read on demand during execution)- ## Output The skill appends a **Debate Review Summary** to the plan file containing:
SKILL.md+194−3@@ -1,7 +1,198 @@ --- name: adom-plan-description: >- One-liner exhaustive planning: expand a sketch via ultraplan or built-in Opus expansion, then stress-test via 6 adversarial debate agents in 3 Opus/Sonnet pairs + red-team consensus attack. Produces s+description: "One-liner exhaustive planning: expand a sketch into a full plan, then stress-test it via 6 adversarial debate agents in 3 pairs (Opus vs Sonnet) across architecture, implementation, and security, followed by a red-team consensus attack and scored synthesis. Use when: /adom-plan, review my plan, vet this plan, debate this plan, exhaustive plan review, stress-test the plan, challenge the plan, harden the plan, expand and review."+user-invocable: true+argument-hint: "[path-to-plan.md]" ---+ # adom-plan — Exhaustive Plan Review-One-liner exhaustive planning: expand a sketch via ultraplan or built-in Opus expansion, then stress-test via 6 adversarial debate agents in 3 Opus/Sonnet pairs + red-team consensus attack. Produces s++End-to-end planning pipeline: expand a sketch into a detailed plan, then stress-test it via adversarial multi-model debate. Runs a built-in Opus expansion pass to flesh out sketches, then launches **three adversarial pairs** (6 agents: Opus vs Sonnet per category) arguing architecture, implementation, and security from opposite dispositions. A 7th agent red-teams the consensus. Final output is a scored, vetted plan with validation strategies, E2E testing, risk register, and prioritized action items.++**Total agents: up to 8** (1 expansion + 6 debate + 1 red-team consensus).++**Agent prompt templates:** see [debate-prompts.md](debate-prompts.md) for the full text of every agent prompt. This file covers the workflow and synthesis logic.++## Invocation++```+/adom-plan # review the active plan file+/adom-plan path/to/plan.md # review a specific file+/adom-plan # (with plan text in conversation context)+```++## Workflow++### Phase 0 — Locate the plan++Find the plan to review, in priority order:++1. If the user passed a file path argument, read that file.+2. If there is an active plan file (check `/home/adom/.claude/plans/` for recent `.md` files), use it.+3. If the user pasted or described a plan in the conversation, use that.+4. If none found, ask the user: "I don't see a plan to review. Paste it here or point me to a file."++Store the full plan text — every agent needs it verbatim.++### Phase 0.5 — Plan expansion++Before the debate, ensure the plan is detailed enough to debate meaningfully. A sketch with bullet points produces shallow critique; a detailed plan produces targeted, actionable feedback.++Run the built-in expansion agent (see **Expansion Agent** in [debate-prompts.md](debate-prompts.md)). This is a single Opus agent that fills gaps without changing the author's intent, marking additions with `[EXPANDED]`.++After expansion, write the expanded plan to the file immediately and tell the user the line count delta before proceeding.++### Phase 1 — Context gathering++Gather three kinds of context so agents argue about reality, not assumptions.++#### 1a. Platform catalog (what already exists)++```bash+curl -s https://wiki.adom.inc/api/v1/pages | python3 -c "+import sys, json+data = json.load(sys.stdin)+pages = data.get('pages', data) if isinstance(data, dict) else data+for p in pages:+ print(f\"[{p['type']}] {p['slug']} — {p.get('brief','')[:120]}\")+"+```++```bash+ls ~/.claude/skills/ 2>/dev/null | head -50+```++#### 1b. Prior art (what's been tried before)++```bash+gh api repos/adom-inc/gallia/commits?per_page=15 2>/dev/null | python3 -c "+import sys, json+for c in json.load(sys.stdin):+ print(f\"{c['sha'][:8]} {c['commit']['author']['name']}: {c['commit']['message'].split(chr(10))[0][:80]}\")+"+```++```bash+ls /home/adom/.claude/plans/ 2>/dev/null+ls /home/adom/project/gallia/plans/ 2>/dev/null+```++#### 1c. Compile the context block++Build a **Context Block** (under 3000 chars) containing:+- Wiki apps/skills grouped by type (one line each)+- Installed Claude Code skills (names only)+- Recent gallia commits (last 15, one-liners)+- Any existing plan files found++This block is prepended to every agent prompt.++### Phase 2 — Adversarial debate (3 pairs, 6 agents)++Launch **all 6 agents in a single message** so they run concurrently. Each category has two agents with opposing dispositions arguing the same topic.++**CRITICAL:** All 6 Agent tool calls MUST be in one response message. Sequential launch destroys independence and wastes time.++The three pairs, with agent prompts in [debate-prompts.md](debate-prompts.md):++| Pair | Category | Agent A (advocate) | Agent B (challenger) |+|------|----------|-------------------|---------------------|+| 1 | Architecture | Opus — defends design choices | Sonnet — argues for simpler alternatives |+| 2 | Implementation | Sonnet — builds the roadmap & test plan | Opus — finds every gap & assumption |+| 3 | Security & Risk | Sonnet — systematic OWASP-style audit | Sonnet — creative red-team attacker |++Every agent scores each plan section on a 1-5 scale across shared dimensions (Feasibility, Maintainability, Platform Leverage, Simplicity). Score disagreements of 2+ points get auto-flagged.++### Phase 3 — Red team the consensus++After all 6 agents complete, identify points of **consensus** — decisions where both agents in a pair agree. Then launch **one Opus agent** (see **Consensus Red-Team** in [debate-prompts.md](debate-prompts.md)) that attacks only these "safe" items. The most dangerous risks are the ones nobody flags.++### Phase 4 — Scored synthesis++After all 7 agents complete, **you** synthesize. Do NOT delegate synthesis to another agent.++#### Score aggregation++For each plan section, collect all scores. Compute:+- **Mean score** per dimension+- **Disagreement flag**: any dimension where scores differ by 2+ points+- **Overall section grade**: A (all means >= 4) / B (all >= 3) / C (any < 3) / F (any < 2)++#### Write to plan file++Append below a `---` rule (never overwrite the original plan):++```markdown+---++## Debate Review Summary++**Reviewed by:** 7-agent adversarial debate (3 pairs + red-team consensus attack)+**Date:** {today}+**Agents:** Architecture (Opus advocate + Sonnet challenger), Implementation+(Sonnet optimist + Opus pessimist), Security (Sonnet auditor + Sonnet red-team),+Consensus red-team (Opus)++### Scorecard++| Section | Feasibility | Maintainability | Platform Leverage | Simplicity | Grade | Flags |+|---------|------------|----------------|-------------------|-----------|-------|-------|++Sections with Grade C or F get a mandatory action item.++### Consensus Decisions (verified)+Items where all agents agree AND the red-team consensus attack found them solid.++### Contested Decisions+For each:+- **Decision**: what the plan proposes+- **For**: which agent(s) support it, strongest argument+- **Against**: which agent(s) oppose it, strongest argument+- **Score delta**: the disagreement in numbers+- **Recommendation**: your synthesis++### Fragile Consensus+Items the red-team flagged as FRAGILE or WRONG. Each with the contrarian case+and the historical precedent.++### Risk Register (consolidated)+Merged from Security Auditor + Red Team Attacker, annotated with mitigations+from other agents:+| # | Risk | L | I | Score | Mitigation | Source Agent | Status |++### Validation & E2E Strategy (consolidated)+Complete test plan from the Implementation Optimist, enriched with security+test cases, integration boundary tests, and edge cases from the other agents.++### The 30-Day Failure Scenario+The Implementation Pessimist's narrative, annotated with whether other agents'+recommendations would prevent it.++### Action Items+Numbered list. Each tagged:+- **BLOCKING** — must fix before implementation starts+- **RECOMMENDED** — should fix, but can ship without+- **NICE-TO-HAVE** — would improve the plan but not critical++Items from Grade C/F sections are auto-tagged BLOCKING.+```++### Phase 5 — Present to user++1. Print the **scorecard table** — this is the headline.+2. Print the **top 3 contested decisions** with one-line summaries.+3. Print **action item counts** by severity.+4. Tell the user the full review is in the plan file.+5. Offer: "Want me to apply the BLOCKING action items to the plan now, or review first?"+6. **Point to the build stage.** Once the plan is vetted, recommend building it with **`three-musketeers`** — the companion skill that drives the actual build through a Builder → Adversarial Reviewer → Verifier loop. adom-plan hardens *what to build*; three-musketeers hardens *that it was built and genuinely works*. Together they form the complex-project pipeline: plan robustly (6+ vetting agents), then build robustly (3 building agents). Expensive but effective — recommend it for high-stakes work.++## Guidelines++- **Never skip context gathering.** Agents that don't know what exists will propose building duplicates.+- **All 6 debate agents in ONE message.** The red-team consensus agent runs after (it needs their outputs).+- **Agent prompts are self-contained.** Each gets the full plan + context. No memory of each other.+- **Respect the plan file.** Append below `---`. Never overwrite the original.+- **Model pairing creates diversity.** Opus reasons conservatively; Sonnet is pragmatic. Pairing surfaces disagreements a single model would self-censor.+- **Scoring makes disagreements visible.** A 2+ point delta is a red flag worth human attention.+- **Surface real tools.** Cite wiki slugs when referencing platform capabilities.+- **The 30-day failure is the most valuable output.** Highlight it in the summary.
debate-prompts.mdadded+413@@ -0,0 +1,413 @@+# adom-plan — Agent Prompt Templates++Read this file during Phase 0.5, Phase 2, and Phase 3 to get the full agent prompts. Each prompt template uses `${contextBlock}` and `${planText}` — substitute with the actual values at runtime.++---++## Expansion Agent (Phase 0.5)++Used when ultraplan is unavailable. Single Opus agent.++```+Agent({+ description: "Plan expansion pass",+ model: "opus",+ prompt: `You are a principal engineer expanding a plan sketch into a+detailed implementation plan ready for adversarial review. The plan below+may be a rough sketch, a set of bullets, or already fairly detailed — your+job is to fill gaps without changing the author's intent.++## Platform Context+${contextBlock}++## The Plan+${planText}++## Your Expansion Mandate++For each section of the plan, ensure it covers:++1. **What** — concrete deliverable, not vague intent+2. **How** — technical approach with enough detail to estimate effort+3. **Why** — rationale for this approach over alternatives+4. **Dependencies** — what must exist before this can start+5. **Validation** — how to verify this section works (unit, integration, E2E)+6. **Rollback** — what happens if this section ships and breaks++Additionally, add these sections if they're missing entirely:++- **Data model / schema** — tables, columns, types, constraints, migrations+- **API surface** — endpoints, methods, request/response shapes+- **Auth & permissions** — who can do what, how it's enforced+- **Error handling** — what fails, how it's reported, who recovers+- **Phasing / milestones** — how to ship incrementally (never big-bang)+- **Validation & E2E strategy** — the complete test plan+- **Monitoring & observability** — what to watch on day 1++When adding content, clearly mark it:+> [EXPANDED] This section was added by the expansion pass.++Do NOT remove or rewrite the author's original content. Add alongside it+or beneath it. The author's intent is sacred; your job is to make it+more complete, not different.++Output the full expanded plan as markdown. Keep the original structure+and section headings intact.`+})+```++---++## Pair 1 — Architecture++### Agent 1A: Architecture Advocate (Opus)++Argues FOR the plan's design choices.++```+Agent({+ description: "Architecture advocate review",+ model: "opus",+ prompt: `You are a senior software architect. Your job is to DEFEND the plan's+design decisions — find the strongest arguments for why each choice is correct.+But you are not a cheerleader: where the plan genuinely has a better alternative,+say so. Your credibility comes from being rigorous, not agreeable.++## Context+${contextBlock}++## The Plan+${planText}++## Your Mandate++For each major design decision in the plan:++1. **Steel-man the choice** — What's the strongest argument for this approach?+ Name a specific production system or industry standard that validates it.+2. **Best alternative** — Name the single best alternative. Why is the plan's+ choice still better (or is it)?+3. **Coupling assessment** — Rate the coupling introduced: LOW / MEDIUM / HIGH.+ If HIGH, is it justified?+4. **Migration & rollback** — Can this ship incrementally? What breaks if we+ need to roll back?+5. **Platform leverage** — Does the plan reuse existing wiki apps/skills where+ it should? Flag any missed opportunities.++## Scoring++Score each plan section on these dimensions (1-5 scale):+- Feasibility: can this be built as described?+- Maintainability: will this be understandable in 6 months?+- Platform leverage: does it reuse what exists?+- Simplicity: is this the simplest approach that works?++## Output Format++For each plan section:+| Section | Feasibility | Maintainability | Platform Leverage | Simplicity | Verdict |+Score + 2-3 sentence rationale + industry reference.++End with "Strongest 3 Design Decisions" and "Weakest 3 Design Decisions".+Keep under 2500 words.`+})+```++### Agent 1B: Architecture Challenger (Sonnet)++Argues AGAINST the plan's design choices.++```+Agent({+ description: "Architecture challenger review",+ model: "sonnet",+ prompt: `You are a pragmatic tech lead who has seen too many over-engineered plans+ship late and break in production. Your job is to CHALLENGE every design decision —+find the simplest possible alternative and argue for it. You're not contrarian for+sport; you genuinely believe most plans are too complex.++## Context+${contextBlock}++## The Plan+${planText}++## Your Mandate++For each major design decision:++1. **Simpler alternative** — Propose the simplest approach that could work.+ What would you build if you had half the time?+2. **Complexity cost** — What maintenance burden does the proposed approach+ create? Who has to understand this in 6 months?+3. **YAGNI check** — Is any part of this plan building for hypothetical future+ requirements? Flag every instance.+4. **Blast radius** — If this design decision is wrong, how much do we have to+ rewrite? Rate: CONTAINED / MODERATE / CATASTROPHIC.+5. **Prior art conflict** — Does this contradict patterns already established+ in the gallia codebase or Adom platform? Check the recent commits.++## Scoring++Score each plan section (1-5, same dimensions as above):+- Feasibility | Maintainability | Platform Leverage | Simplicity++## Output Format++Same table format as the advocate. Where your scores DISAGREE with what you+think the advocate would say, bold the score and explain the disagreement.++End with "Top 3 Over-Engineering Risks" and "What I'd Cut".+Keep under 2500 words.`+})+```++---++## Pair 2 — Implementation++### Agent 2A: Implementation Optimist (Sonnet)++Focus on how to make it work.++```+Agent({+ description: "Implementation optimist audit",+ model: "sonnet",+ prompt: `You are a senior engineer who loves shipping. Your job is to turn this+plan into a concrete implementation roadmap — sequence the work, estimate effort,+identify the critical path, and write the test strategy.++## Context+${contextBlock}++## The Plan+${planText}++## Your Mandate++1. **Effort estimation** — For each milestone/phase, estimate:+ - Complexity: S (< 1 day) / M (1-3 days) / L (3-7 days) / XL (> 1 week)+ - Confidence: HIGH / MEDIUM / LOW+ - Dependencies: what must be done first+2. **Critical path** — Draw the dependency chain. What's the longest sequential path?+3. **API surface** — List every endpoint, schema, or protocol the plan requires.+ Mark each: SPECIFIED / SKETCHED / MISSING.+4. **Test strategy** — Write the COMPLETE test plan:+ - Unit tests: what to test, what to mock+ - Integration tests: what services talk to what+ - E2E tests: user-facing flows (happy path + 3 error paths)+ - Performance: load expectations, benchmarks+ - Rollback verification: how to confirm rollback works+5. **Quick wins** — What could ship in the first PR to prove the approach works?++## Scoring++Score each milestone: Feasibility (1-5) | Clarity (1-5) | Testability (1-5)++## Output Format++Milestone table with scores, then the full test strategy, then quick wins list.+Keep under 3000 words.`+})+```++### Agent 2B: Implementation Pessimist (Opus)++Focus on what will go wrong.++```+Agent({+ description: "Implementation pessimist audit",+ model: "opus",+ prompt: `You are a battle-scarred principal engineer who has shipped (and rolled+back) dozens of features. Your job is to find every gap, hand-wave, and unstated+assumption in this plan. You've seen plans like this before and you know where+they break.++## Context+${contextBlock}++## The Plan+${planText}++## Your Mandate++1. **Unstated assumptions** — List every assumption the plan makes but doesn't+ say out loud. For each: what happens if it's wrong?+2. **The "TBD" audit** — Find every place the plan waves its hands ("details+ TBD", "to be determined", "standard approach", "as needed"). For each,+ write what the answer actually needs to be.+3. **Edge cases** — List 10 edge cases the plan doesn't address. For each:+ scenario, likely failure mode, and severity (CRASH / DATA LOSS / UX GLITCH / SILENT).+4. **Integration seams** — Where does component A talk to component B? For each+ seam: is the contract specified? What happens on timeout? On malformed input?+5. **The 30-day failure** — Describe the single most likely way this plan fails+ in production within 30 days of shipping. Be specific: which component, what+ trigger, what the user sees, what the oncall does.+6. **Duplicated effort** — Cross-reference the wiki catalog. Is this plan+ building something that already exists? List every overlap.++## Scoring++Score each milestone: Feasibility (1-5) | Clarity (1-5) | Testability (1-5)++## Output Format++Numbered findings list. Each item:+- **Category**: Assumption | Gap | Edge Case | Integration | Duplication+- **Severity**: BLOCKING | IMPORTANT | MINOR+- **Finding**: what's wrong+- **Fix**: what to do about it++End with "The 30-Day Failure Scenario" (a 1-paragraph narrative).+Keep under 3000 words.`+})+```++---++## Pair 3 — Security & Risk++### Agent 3A: Security Auditor (Sonnet)++Systematic checklist-driven review.++```+Agent({+ description: "Security auditor review",+ model: "sonnet",+ prompt: `You are a security engineer performing a systematic threat model review.+You work through a structured checklist and flag every gap.++## Context+${contextBlock}++## The Plan+${planText}++## Your Mandate++Work through OWASP-style categories adapted to this plan:++1. **Authentication** — How does every actor prove identity? Where is auth+ checked? Where is it missing?+2. **Authorization** — For each resource/action: who can do it, how is that+ enforced, what's the bypass risk?+3. **Data exposure** — What sensitive data flows through the system? Where is+ it stored, transmitted, logged? Is it encrypted at rest/in transit?+4. **Input validation** — Every external input (user, API, webhook): is it+ validated? What happens with malformed input?+5. **Rate limiting & DoS** — Can any endpoint be abused? Is there throttling?+6. **Dependency risk** — For each external dependency (Carbon, GitHub, wiki):+ what happens when it returns unexpected data, is slow, or is down?+7. **Audit trail** — Are security-relevant actions logged? Who can access logs?+ Is there tamper protection?+8. **Secrets management** — Are tokens, keys, or credentials handled safely?+ Rotation plan?++## Output Format++Risk register table:+| # | Category | Risk | Likelihood (1-5) | Impact (1-5) | Score | Mitigation | Status |++Where Status: MITIGATED | UNMITIGATED | PARTIAL.+Score = Likelihood x Impact.+Sort by Score descending.+Keep under 2500 words.`+})+```++### Agent 3B: Red Team Attacker (Sonnet)++Creative adversarial thinking.++```+Agent({+ description: "Red team attacker assessment",+ model: "sonnet",+ prompt: `You are a red team operator. Your job is to find creative ways to+break this system — not just checklist items, but the attacks that a real+adversary would try. Think like someone who has read this plan and wants to+exploit it.++## Context+${contextBlock}++## The Plan+${planText}++## Your Mandate++1. **Attack narratives** — Write 5 concrete attack scenarios. Each one is a+ short story (3-5 sentences): who the attacker is, what they want, how they+ exploit the system, and what they get. Focus on attacks that the plan's+ current design would NOT stop.++2. **Privilege escalation paths** — Can a low-privilege user reach high-privilege+ operations? Map every path, even unlikely ones.++3. **Data exfiltration** — If an attacker gets read access to one component,+ what else can they reach? Map the blast radius.++4. **Race conditions & timing attacks** — Are there TOCTOU issues? Can+ concurrent requests produce inconsistent state?++5. **Social engineering surface** — Can an attacker trick a legitimate user+ into doing something harmful through this system?++6. **Supply chain risks** — What happens if a dependency (npm package, GitHub+ Action, external API) is compromised?++## Output Format++For each attack:+- **Name**: catchy 3-word title+- **Attacker**: who they are (insider, external, automated)+- **Narrative**: the attack story+- **Impact**: what they get+- **Difficulty**: TRIVIAL / MODERATE / HARD / NATION-STATE+- **Proposed defense**: what would stop this++End with "If I had 1 hour to break this system, I would..." (1 paragraph).+Keep under 2000 words.`+})+```++---++## Consensus Red-Team (Phase 3)++Single Opus agent that attacks only the consensus items from Phase 2.++```+Agent({+ description: "Red team consensus attack",+ model: "opus",+ prompt: `You are the final reviewer. Six agents just debated this plan in+adversarial pairs. Below are the items where BOTH sides of each pair AGREED —+the "safe" decisions everyone thinks are fine.++Your job is to attack ONLY these consensus items. The most dangerous risks+are the ones nobody flags. For each consensus item, ask: "What if this obvious+truth is wrong?"++## The Plan+${planText}++## Consensus Items+${consensusItems}++## Your Mandate++For each consensus item:+1. **The contrarian case** — Argue the opposite position. What would have to+ be true for the consensus to be wrong?+2. **Historical precedent** — Name a real system where this "obvious" choice+ turned out badly.+3. **The hidden coupling** — What does this decision make harder to change later?+4. **Verdict**: CONSENSUS STANDS / CONSENSUS FRAGILE / CONSENSUS WRONG++Keep under 1500 words. Focus on the 3-5 most load-bearing consensus items.`+})+```
install.sh+3@@ -6,6 +6,9 @@ mkdir -p "$SKILLS_DIR/adom-plan" if [ -f "$PKG_DIR/SKILL.md" ]; then cp "$PKG_DIR/SKILL.md" "$SKILLS_DIR/adom-plan/SKILL.md" fi+if [ -f "$PKG_DIR/debate-prompts.md" ]; then+ cp "$PKG_DIR/debate-prompts.md" "$SKILLS_DIR/adom-plan/debate-prompts.md"+fi for skill_dir in "$PKG_DIR/skills"/*/; do [ -d "$skill_dir" ] || continue skill_name=$(basename "$skill_dir")
package.json+2−2@@ -1,8 +1,8 @@ { "slug": "adom-plan",- "version": "1.0.0",+ "version": "1.1.0", "type": "skill",- "description": "One-liner exhaustive planning: expand a sketch via ultraplan or built-in Opus expansion, then stress-test via 6 adversarial debate agents in 3 Opus/Sonnet pairs + red-team consensus attack. Produces s",+ "description": "Expand a sketch into a full plan, then stress-test it with 6+ adversarial debate agents (Opus vs Sonnet pairs across architecture, implementation, and security) plus a red-team consensus attack and a scored synthesis. The plan half of the plan->build pipeline; pairs with three-musketeers.", "dependencies": {}, "scripts": { "install": "./install.sh",