skill
adom-plan — Exhaustive Plan Review
Public Made by Adomby adom
Expand a sketch into a full plan, then stress-test it with 6+ adversarial debate agents (Opus vs Sonnet pairs) plus a red-team consensus attack and a scored synthesis.
← Commit history
page.json+13−17@@ -2,8 +2,8 @@ "schema_version": 1, "type": "skill", "slug": "adom-plan",- "title": "adom-plan — Exhaustive Plan Review",- "brief": "One-liner exhaustive planning: expand a sketch via ultraplan or built-in Opus expansion, then stress-test via 6 adversarial debate agents in 3 Opus/Sonnet pairs + red-team consensus attack. Produces s",+ "title": "adom-plan \u2014 Exhaustive Plan Review",+ "brief": "Expand a sketch into a full plan, then stress-test it with 6+ adversarial debate agents (Opus vs Sonnet pairs) plus a red-team consensus attack and a scored synthesis.", "version": "1.1.0", "tags": [ "planning",@@ -36,29 +36,25 @@ } ], "source_path": "SKILL.md",- "readme": "# adom-plan — Exhaustive Plan Review\n\nEnd-to-end planning pipeline: expand a sketch into a detailed plan, then stress-test it via adversarial multi-model debate. Uses **ultraplan** when available (harness-level deep expansion), otherwise runs a built-in Opus expansion pass. Then launches **three adversarial pairs** (6 agents: Opus vs Sonnet per category) arguing architecture, implementation, and security from opposite dispositions. A 7th agent red-teams the consensus. Final output is a scored, vetted plan with validation strategies, E2E testing, risk register, and prioritized action items.\n\n**Total agents: up to 8** (1 expansion + 6 debate + 1 red-team consensus).\n\n## How it works\n\n1. **Phase 0** — Locate the plan (plan file, file path argument, or conversation context)\n2. **Phase 0.5** — Expand the plan via ultraplan (if available) or built-in Opus expansion agent\n3. **Phase 1** — Fetch platform context (wiki catalog, installed skills, recent commits, existing plans)\n4. **Phase 2** — Launch 6 adversarial debate agents in parallel (3 pairs):\n - Architecture: Opus advocate vs Sonnet challenger\n - Implementation: Sonnet optimist vs Opus pessimist\n - Security: Sonnet auditor vs Sonnet red-team attacker\n5. **Phase 3** — Red-team the consensus with one final Opus agent\n6. **Phase 4** — Scored synthesis with scorecard, contested decisions, risk register, E2E strategy, and action items\n7. **Phase 5** — Present summary to user\n\n## Key features\n\n- **Adversarial pairing** — two agents argue each category from opposite dispositions, surfacing disagreements a single model would self-censor\n- **Multi-model diversity** — Opus reasons conservatively and architecturally; Sonnet is pragmatic and detail-oriented\n- **Structured scoring** — 1-5 scale across Feasibility, Maintainability, Platform Leverage, Simplicity; 2+ point deltas auto-flagged\n- **Platform awareness** — fetches wiki catalog so agents reference real tools, not hypothetical ones\n- **The 30-Day Failure Scenario** — forces concrete, actionable thinking about what will actually go wrong\n- **Consensus red-team** — attacks the \"safe\" decisions everyone agrees on, because the most dangerous risks are the ones nobody flags\n\n## Invocation\n\n```\n/adom-plan # review the active plan file\n/adom-plan path/to/plan.md # review a specific file\n```\n\n## Installation\n\nBundled with gallia. Available at `~/.claude/skills/adom-plan/` after `install.mjs` runs. The skill consists of two files:\n\n- `SKILL.md` (212 lines) — workflow, phases, synthesis format, guidelines\n- `debate-prompts.md` (413 lines) — all 8 agent prompt templates (read on demand during execution)\n\n## Output\n\nThe skill appends a **Debate Review Summary** to the plan file containing:\n\n- **Scorecard** — per-section grades (A/B/C/F) with dimensional scores\n- **Consensus Decisions** — verified safe items\n- **Contested Decisions** — where agents disagreed, with recommendations\n- **Fragile Consensus** — items the red-team flagged\n- **Risk Register** — consolidated threat table with mitigations\n- **Validation & E2E Strategy** — complete test plan\n- **The 30-Day Failure Scenario** — the most likely production failure\n- **Action Items** — numbered list tagged BLOCKING / RECOMMENDED / NICE-TO-HAVE\n",+ "readme": "# adom-plan \u2014 Exhaustive Plan Review\n\nEnd-to-end planning pipeline: expand a sketch into a detailed plan, then stress-test it via adversarial multi-model debate. Runs a built-in Opus expansion pass to flesh out the sketch, then launches **three adversarial pairs** (6 agents: Opus vs Sonnet per category) arguing architecture, implementation, and security from opposite dispositions. A 7th agent red-teams the consensus. Final output is a scored, vetted plan with validation strategies, E2E testing, a risk register, and prioritized action items.\n\n**Total agents: up to 8** (1 expansion + 6 debate + 1 red-team consensus).\n\n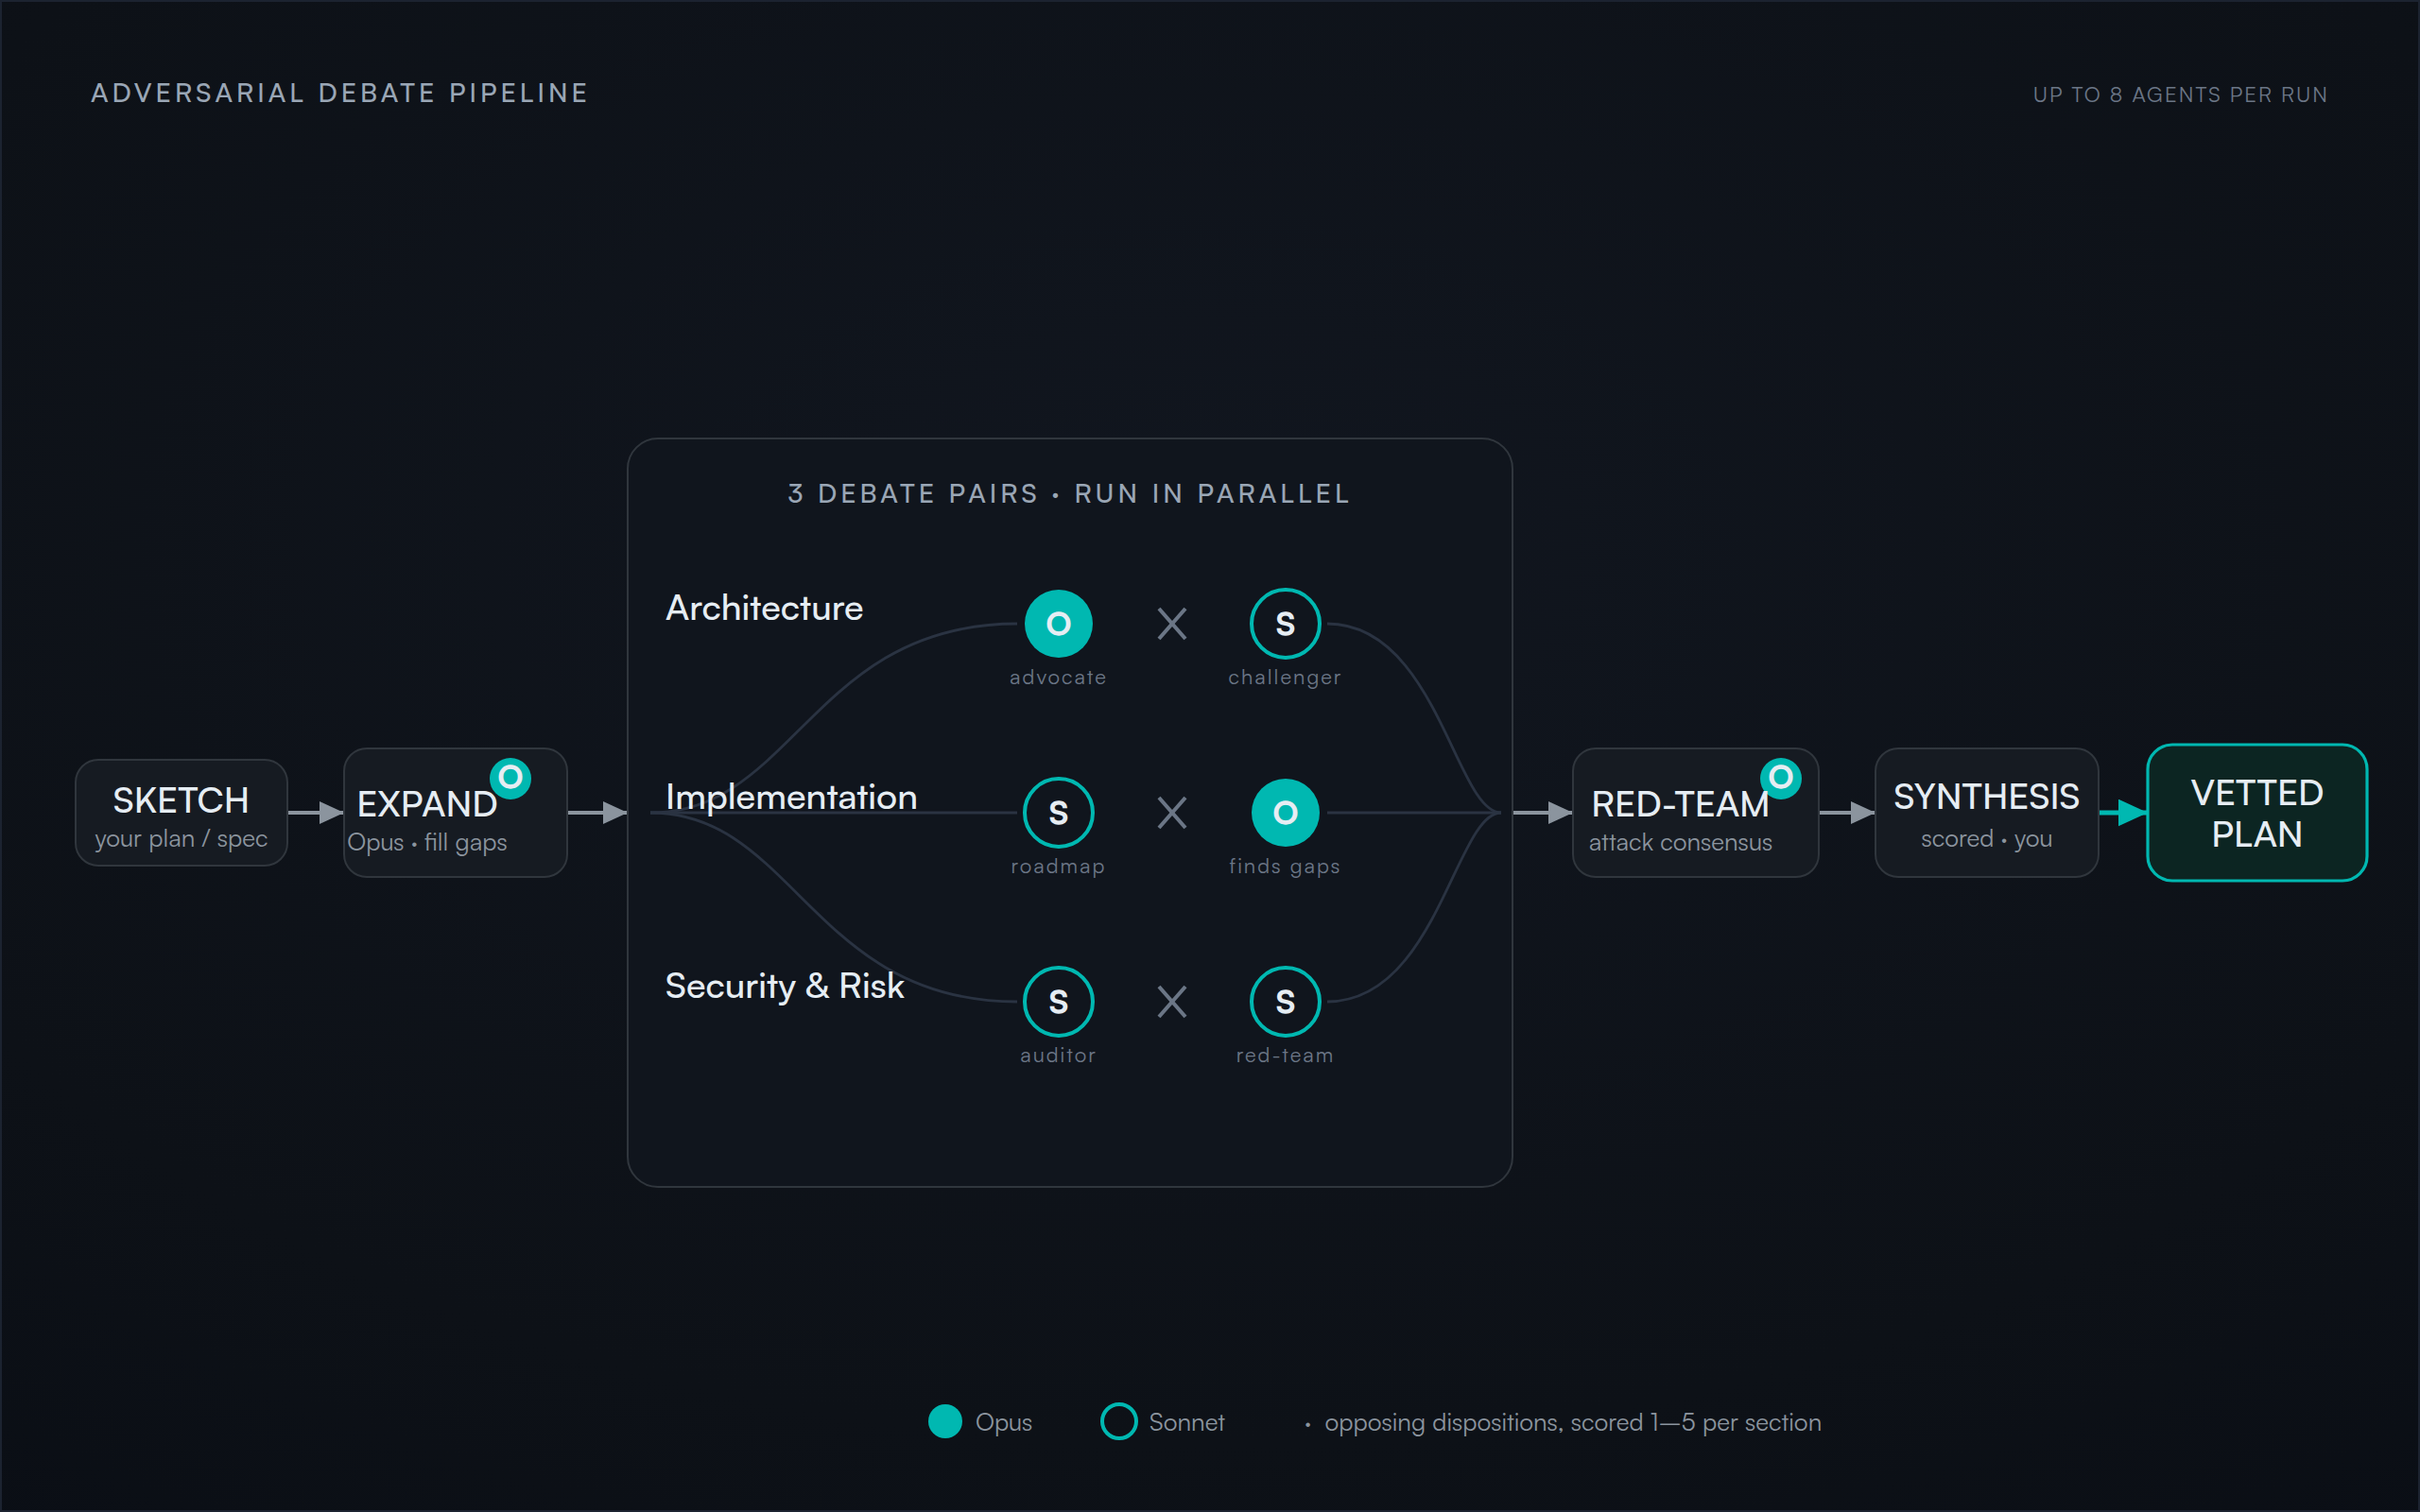\n\n## How it works\n\n1. **Phase 0** \u2014 Locate the plan (plan file, file path argument, or conversation context)\n2. **Phase 0.5** \u2014 Expand the plan via a built-in Opus expansion agent\n3. **Phase 1** \u2014 Fetch platform context (wiki catalog, installed skills, recent commits, existing plans)\n4. **Phase 2** \u2014 Launch 6 adversarial debate agents in parallel (3 pairs):\n - Architecture: Opus advocate vs Sonnet challenger\n - Implementation: Sonnet roadmap-builder vs Opus gap-finder\n - Security & Risk: Sonnet auditor vs Sonnet red-team attacker\n5. **Phase 3** \u2014 Red-team the consensus with one final Opus agent\n6. **Phase 4** \u2014 Scored synthesis: scorecard, contested decisions, risk register, E2E strategy, action items\n7. **Phase 5** \u2014 Present the summary to the user\n\n## Key features\n\n- **Adversarial pairing** \u2014 two agents argue each category from opposite dispositions, surfacing disagreements a single model would self-censor\n- **Multi-model diversity** \u2014 Opus reasons conservatively and architecturally; Sonnet is pragmatic and detail-oriented\n- **Structured scoring** \u2014 1\u20135 scale across Feasibility, Maintainability, Platform Leverage, Simplicity; 2+ point deltas auto-flagged\n- **Platform awareness** \u2014 fetches the wiki catalog so agents reference real tools, not hypothetical ones\n- **The 30-Day Failure Scenario** \u2014 forces concrete, actionable thinking about what will actually go wrong\n- **Consensus red-team** \u2014 attacks the \"safe\" decisions everyone agrees on, because the most dangerous risks are the ones nobody flags\n\n## Then build it \u2014 pairs with `three-musketeers`\n\nadom-plan is the **plan half** of Adom's complex-project pipeline. Once the plan is vetted here, build it with **[`three-musketeers`](/adom/three-musketeers)** \u2014 the companion skill that drives the actual build through a Builder \u2192 Adversarial Reviewer \u2192 Verifier loop until it genuinely works:\n\n1. **Plan robustly** with adom-plan \u2014 6+ vetting agents harden *what to build*.\n2. **Build robustly** with three-musketeers \u2014 3 building agents harden *that it was built and actually works* (the Verifier confirms behavior as a user, not against the plan, so the builder is free to correct anything adom-plan got wrong).\n\nExpensive but effective \u2014 reach for the full plan\u2192build pipeline on high-stakes or long-running work.\n\n## Invocation\n\n```\n/adom-plan # review the active plan file\n/adom-plan path/to/plan.md # review a specific file\n```\n\n## Output\n\nThe skill appends a **Debate Review Summary** to the plan file containing:\n\n- **Scorecard** \u2014 per-section grades (A/B/C/F) with dimensional scores\n- **Consensus Decisions** \u2014 verified safe items\n- **Contested Decisions** \u2014 where agents disagreed, with recommendations\n- **Fragile Consensus** \u2014 items the red-team flagged\n- **Risk Register** \u2014 consolidated threat table with mitigations\n- **Validation & E2E Strategy** \u2014 complete test plan\n- **The 30-Day Failure Scenario** \u2014 the most likely production failure\n- **Action Items** \u2014 numbered list tagged BLOCKING / RECOMMENDED / NICE-TO-HAVE\n", "author": { "id": "695820315b5f1e4db2fcf602", "name": "Kyle Bergstedt", "email": "[email protected]" },- "visibility": "public",+ "visibility": {+ "public": true+ }, "hero": { "type": "image", "path": "screenshots/hero.png" },- "discovery_triggers": [],+ "discovery_triggers": [+ "review my plan",+ "vet this plan",+ "stress-test the plan",+ "harden the plan"+ ], "discovery_pitch": null,- "metadata": {},- "created_at": "2026-05-28T05:29:33.375Z",- "updated_at": "2026-05-28T05:29:33.375Z",- "sub_skills": [],- "parent_app": null,- "description": "Expand a sketch into a full plan, then stress-test it with 6+ adversarial debate agents (Opus vs Sonnet pairs across architecture, implementation, and security) plus a red-team consensus attack and a scored synthesis. The plan half of the plan->build pipeline; pairs with three-musketeers.",- "dependencies": {},- "scripts": {- "install": "./install.sh",- "uninstall": "./uninstall.sh"- },- "org": "adom"+ "metadata": {} }